2109 stories
·
3 followers

Torrent underground

1 Share
Hooded mage with sword in front of a download progress bar with electricity connected to various computers.

When Jane first heard about Memory and Imagination, a rare 1990s documentary about the Library of Congress, she was intrigued. But the Canadian writer in her 30s couldn’t find the movie anywhere — not on streaming services, not on YouTube, not on pirate sites — and her intrigue turned into obsession.

Worried it might become a lost film, Jane decided to scour auction sites, search every library catalog she could think of, and even enlist some of her online acquaintances to find a copy. Her plan was to “share it with other people to help ensure it would be preserved into the future,” as she puts it. Jane knew the perfect tool for the task: a private torrent tracker.

“I am ethically conflicted about piracy. I often feel guilty about it.”

Private trackers are essentially the speakeasies of the online piracy world. Promoted primarily by word of mouth, they rely on secrecy, exclusivity, and strict community rules to shield everything that’s going on behind closed doors from the public’s prying eyes. What unites these communities is that they all use BitTorrent to trade media among like-minded file sharers. But their focuses range widely, from general-purpose trackers with catalogs so broad that they make Netflix look like a niche service to the many specialized communities for categories like Chinese movies, motorsports, visual effects tools, e-learning courses, and Japanese porn. There’s even a private tracker just for Frank Zappa music.

Private trackers are known for massive and meticulously organized catalogs, which they owe to users like Jane, who, like every other pirate I talked to for this story, opted to be identified by a pseudonym due to the terabytes of copyrighted data they’ve been sharing. These are people willing to go the extra mile to find long-forgotten movies, rare concert recordings, or out-of-print books. “Many private tracker users are fully consumed with archive fever,” she says.

At first, Jane had no luck finding a physical copy of that elusive documentary, which includes interviews with Steve Jobs and Julia Child. Nobody was selling it on eBay. Her local public library didn’t have it. Neither did any other public library in North America. And when she finally located a DVD that was available to the public, it was in the Bibliotheca Alexandrina — Egypt’s modern-day re-creation of the ancient library that’s long been synonymous with lost media. “That bowled me over,” Jane says. “This obscure movie I’m looking for is only available in the Library of Alexandria!”

Eventually, Jane found Memory and Imagination for sale on a small online marketplace for historical media. Jane instantly bought a copy and uploaded it. “It looked like a digital rip of a severely degraded VHS tape,” she says. “I was still over the moon [that] I rescued this historically significant documentary.”


Not everyone who uses private trackers shares Jane’s amateur-archivist zeal. Some are simply in it for easy access to pirated movies, TV shows, or other forms of entertainment. “My goal initially was to have a better source for video games,” says Odel, a West Coast-based college student. “I quickly found out that [private trackers] could replace everything else.” Others join trackers in search of a community of like-minded cinephiles or music fans. And as they immerse themselves in a world of illicit media trading that’s largely shielded from public view, many of them seem to catch a peculiar kind of bug.

“There aren’t many closed doors on the internet.”

They painstakingly work their way up the ranks in the trackers they’ve joined and then use their freshly earned social capital to get access to even more exclusive sites, where the same rat race starts all over again. “Exclusivity definitely plays a part,” says Maysay, a private tracker user from Pakistan. “You want to get into those more exclusive ‘elite’ trackers at some point just for the sake of it.”

“There is definitely a constant quest to level up,” says Jane, who maintains active accounts on 14 private trackers.

Among the people I talked to for this story, that’s actually a small number. Some private tracker users maintain dozens of accounts, download terabytes of data, share thousands of torrents at a time, embark on obsessive quests to get their hands on long-lost media, and use automated apps and tools that make everyday piracy seem like child’s play.


In a world where streaming services offer access to countless movies and TV shows for little more than your credit card number, private trackers can seem a bit like a throwback. A nod to a different time, when legal options didn’t really exist and file sharing happened in private chat rooms or on password-protected FTP servers.

“There aren’t many closed doors on the internet,” says Jane, who became interested in joining private trackers after hearing about them from friends. Jane quickly realized that she couldn’t just sign up for the latest and greatest movie trackers, which were only open to vetted users with a history of good behavior on other servers. So she devised a plan to join a more lenient private tracker for audiobooks first and work her way up from there.

Users who fall below certain metrics often find their download privileges curtailed, and especially egregious offenses result in instant bans.

Even getting access to that first server came with some hurdles. Private tracker websites rarely have freely accessible sign-up forms. Some only open their doors to new users every few weeks or months, while others use special vetting processes to make sure applicants are a good fit. Sometimes this means that applicants are required to prove they’re in good standing on other trackers. Sometimes they need to take screenshots of their personal media collections to show they’re actually interested in what the tracker they’re applying to is all about. And sometimes there are even actual interviews applicants have to ace before getting their accounts.

The long-defunct private music tracker What.CD used to quiz applicants about audio formats and MP3 encoder settings, and even published a study guide of sorts to help them prepare for it. And Jane’s very first private tracker required her to first join an IRC chatroom, where admins quizzed her about the server’s rules. “It was so stressful! It felt like a job interview,” she says.

Not every private tracker has these kinds of interviews, but like Jane’s first server, most are big on rules. Users are generally required to keep up a certain upload-to-download ratio, with many sites demanding that they contribute as much bandwidth as they consume. (The exact rules and requirements vary, and many trackers also offer some “freeleech” content — files that can be downloaded without negatively impacting a user’s ratio.) Quickly downloading a file without sharing it is also frowned upon, as is the unvetted distribution of invites to outsiders.

Various forms of media pouring out from behind an unlocked door.

Users who fall below certain metrics often find their download privileges curtailed, and especially egregious offenses result in instant bans. “Invite selling is considered to be a major breach of security,” says Odel. Doing so will not only get you kicked from a server, it will also tarnish your reputation elsewhere. “Staff of the tracker you did it on will typically communicate with the staff of some other trackers, which can result in you getting banned from those places as well,” Odel explains.

If you do follow the rules and share generously, you have a chance to work your way up the ranks, which then opens the doors to other trackers. That alone, and the requirement to keep up a healthy upload-to-download ratio, can lead to people downloading and then redistributing (also known as “seeding” in tracker lingo) files just to maintain their stats. “Some places will require you to seed [a certain amount of] terabytes before you get access to a certain rank,” says Odel. “This can result in a lot of downloading of stuff I wouldn’t ever consume otherwise, just to pump up that number.”

“You have to seed things you aren’t interested in consuming to succeed in the tracker economy.”

Odel estimates that he has downloaded around 500 terabytes of data from the 30 or so private trackers he’s currently active on. In the end, he’s watched very little of it. “Probably less than one percent,” he says.

That discrepancy is not uncommon. “I am seeding over 2,000 torrents, and I have no personal interest in almost any of them,” admits Jane. Maysay tells me that he seeds around 3,000 torrents at any given time and has downloaded things he doesn’t intend to watch “many times.”

“It’s how these sites are built,” Jane explains. “You have to seed things you aren’t interested in consuming to succeed in the tracker economy.” Some private tracker users use automated tools to help them maintain their ratio, like scripts that watch dedicated IRC channels to quickly jump on any newly released torrent, no matter what content it is. This is called “racing” in tracker lingo, and it can help improve one’s ratio; anyone looking to download that file later will get it from those early downloaders. Especially committed users even rent a dedicated seedbox — a private server sitting in some remote data center that is only used for downloading and then seeding torrents.

Being able to download more is only one reason for trying to improve your ratio and standing on private trackers. “I just do it for fun,” Jane says. “It’s kind of like playing a video game and watching your score go up.” And just like with some video games, there is a certain addictive quality to all this. ”Using private trackers reminded me a lot of playing MMORPG games like World of Warcraft or RuneScape where you really have to grind to level up,” Jane says. “It’s slow, tedious, and repetitive. Yet you feel this insatiable compulsion to level up.”


Private BitTorrent trackers emerged soon after BitTorrent itself was created 25 years ago. This was at the height of the file-sharing wars, when Hollywood and the major record labels were taking one peer-to-peer network operator after another to court. Entertainment industry lawsuits resulted in the shutdown of Napster in 2001, Audiogalaxy in 2002, and Kazaa in 2006.

Those closures drove millions of file sharers to embrace BitTorrent, which in turn put torrent sites into the crosshairs of rightsholders and their lawyers. Suprnova, a public torrent site frequented by millions of users, shut down amid legal pressure at the end of 2004. And in 2006, authorities raided The Pirate Bay.

Some torrent site admins responded to the increasing legal pressure by simply pulling up a drawbridge to their piracy communities. Instead of letting just anyone download torrents, they required users to register, and in some cases only admitted new users that had gotten an invite from a trusted community member.

Nobody knows exactly how many private trackers are currently up and running, or how many people use them for their pirated media fix. But while BitTorrent piracy as a whole has declined since the emergence of Netflix, Spotify, and other paid streaming services, private trackers are still going strong.

A live dashboard maintained by a tracker software developer currently lists around 530 private trackers, including some with hundreds of thousands of registered users. One music tracker, listed only as [REDACTED] on this dashboard, is said to host 3.7 million torrents, or works to download. A popular movie tracker included in the list has more than 1 million torrents, which are being traded among just 40,000 registered users.

“Occasionally people will request or ask for something that just isn’t available commercially anymore, or ever, and attach a huge bounty to it.”

One of the first notable private trackers was Oink’s Pink Palace, an invite-only music sharing                                 community with a reported 180,000 registered users. Among them was Nine Inch Nails front man Trent Reznor, who told Vulture in 2007 that the site had been “like the world’s greatest record store,” offering access to “pretty much anything you could ever imagine […] in the format you wanted.”

A person's hand grabbing a file from another person's hand from behind a computer screen.

Many private tracker communities meticulously curate catalogs that put publicly accessible piracy sites to shame. “The private tracker experience is a lot better,” says Marvin, a 23-year-old software developer from the Pacific Northwest. Public torrent sites are often ad-ridden and hard to navigate and search, he says. Maysay agrees, telling me that he appreciates private trackers “not just because of the amount of content [available], but also because of the quality, organization, and how well everything is sorted.”

The curation happening in these private communities is very much a group effort. Many private trackers offer their members a chance to request files they want others to upload, complete with bounties (download credits that you would otherwise have to upload other files for) for the first uploader. The rarer the file, the bigger the bounty. And the bigger the bounty, the more frenzied the hunt for that elusive file.

“Are large corporations to be trusted with archiving our culture?”

One famous quest for such a bounty unfolded in 2013, when a user of the since-shuttered What.CD server put out a request for “The Ocean Full of Bowling Balls,” a story from Catcher in the Rye author J.D. Salinger that the writer himself had refused to publish. For a long time, the only known copy of “The Ocean Full of Bowling Balls” resided in Princeton University’s Firestone Library, where visitors could read but not copy the document.

The intrigue — Salinger didn’t publish a single work for the last 45 years of his life — combined with the fact that there clearly was at least one copy out there set off a frenzy among What.CD users, with the bounty reportedly swelling to a massive 6TB. Some came up with schemes to memorize every word of the story while visiting Princeton’s library, while others scoured the Earth for other copies.

A few months later, a What.CD user was ready to claim the bounty. “It took me many weeks of research to find that this book existed and many more weeks to acquire it,” the user wrote in a note accompanying a torrent featuring a total of three unpublished Salinger stories, including “The Ocean Full of Bowling Balls.” Someone had apparently published the three stories as part of a book that was printed just 25 times in 1999. Years later, one of those 25 copies showed up on eBay, where the What.CD uploader quickly snagged it.

The story of this unlikely act of renegade archiving quickly made headlines worldwide, and to this day is legendary in the private tracker community. (The uploader of the book was ironically never able to claim their massive bounty, as site admins removed the torrent once it got too much outside attention.) But while few other bounty hunts have gotten that much attention, they do happen.

“A great deal of media released today will persist via private servers, much like how a lot of silent films we have today were found as reels stored in people’s attics.”

“Occasionally people will request or ask for something that just isn’t available commercially anymore, or ever, and attach a huge bounty to it,” says Odel. “People will research any potential leads, reach out to random French directors via email, and ultimately come back with nothing. Then, a few years later, somebody will randomly upload whatever was being looked for onto YouTube, with no further explanation.”

Odel told me he doesn’t personally partake in these kinds of media hunts. “But I’ve seen some things which I’d classify as ‘important’ be recovered this way,” he says. “Piracy does happen to be pretty good at preservation.”

UC Berkeley professor Abigail De Kosnik, who has investigated private trackers as part of her research on rogue online archives, agrees. “A great deal of media released today will persist via private servers, much like how a lot of silent films we have today were found as reels stored in people’s attics,” she says. “I think that private torrent trackers, which make possible [to download] many art films, indie films, smaller-budget films, films from many countries, will play a large part in constituting future archives of 20th and 21st century cultural productions.”


Copyright holders, unsurprisingly, often hold less favorable views of the private tracker community. “Private trackers are part of a broader piracy ecosystem,” says Larissa Knapp, executive vice president and chief content protection officer of the Motion Picture Association (MPA). “Content that first appears within a closed community can quickly migrate to streaming sites, cyberlockers, IPTV services, and other unauthorized platforms, significantly amplifying its reach and impact.”

Rightsholder groups have repeatedly gone after private trackers and their administrators with varying levels of success. Oink’s Pink Palace, the popular private music tracker, shut down in 2007 following raids in the Netherlands and the UK. Oink admin Alan Ellis was arrested and charged with conspiracy to defraud as part of the enforcement actions, but was later found not guilty in court. Shuttering the tracker also did little to stop file sharing. Oink was quickly succeeded by What.CD, which remained online for nearly a decade until finally closing down in 2016 following a raid on its data center.

These days, private file sharing communities aren’t as often in the news as they were a decade ago. Part of that is simply a matter of priority. Private trackers often cap the number of registered users; some of the most coveted communities have only 40,000 or fewer active members. Public sites like The Pirate Bay, on the other hand, still attract millions of file sharers, making it easier for commercial copyright enforcers to send out tens of thousands of legal notices to end users at a time — a practice that’s especially common in Europe.

Still, groups like the MPA, and its ACE anti-piracy arm, haven’t given up on going after private file sharing communities and their admins. “Private trackers are not beyond enforcement reach,”                                 Knapp says. “Closed access can make an investigation more difficult, but it does not eliminate the legal or operational exposure for the people who run them. In my years in federal law enforcement, I learned that anonymity is rarely as complete as people believe. A private community is not a safe harbor. Every operation, no matter how closed, still depends on people, hosting and domain services, communications tools, and usually some way to move money. Each of those is a connection, and connections are what investigators follow.”

There’s also the moral questions of engaging in piracy, which don’t get easier to answer when you’re actively sharing thousands of files 24/7. “I am ethically conflicted about piracy,” Jane says. “I often feel guilty about it.” Jane tries to assuage some of her guilt by actively purchasing media she likes.

Others told me a similar version of this, while also stressing that piracy is simply more user-friendly and convenient than legal services. That’s especially true for users in developing countries. “A big part of it for me is accessibility,” says Maysay, whose choices in Pakistan are limited. “There’s a lot of content that simply isn’t easily available legally here.”

“In my years in federal law enforcement, I learned that anonymity is rarely as complete as people believe.”

The fast-moving copyright battle around AI adds further ambiguity to this debate. “Now that the fastest-growing corner of the knowledge industries relies on mass piracy — copying huge amounts of data that they download for free — I think that the anti-piracy rhetoric of the past quarter-century is looking a bit outdated,” says De Kosnik. “If anything, AI [companies] are anti-archival because they strip away attribution from the creators, whereas private trackers are intensely accurate in providing details about the source material. So, are large corporations to be trusted with archiving our culture?”

Still, some of the users I spoke to were also acutely aware that it’s hard for them to take the moral high road. “It may genuinely hurt smaller creators,” Odel admits. “I’m not a fan of the people who try to advocate for it being moral or anything. I tend to justify my own piracy under the lense of ‘I wouldn’t be watching x otherwise.’ Whether that would be true assuming I was suddenly unable to pirate anything, I do not know.”

Not everyone is as conflicted about using private trackers. “I own it, it’s piracy. I torrent this content because I find it very convenient and don’t want to pay for every audiobook, TV episode, movie, etc.,” says Marvin.

Marvin tells me he originally got into piracy for financial reasons. “It was a habit that started with me growing up poor,” he says. Nowadays, that’s less of an issue for him, and he does spend money on some content, including books and video games.

“But I am a pirate at heart,” Marvin acknowledges. “This is paid content that I am getting for free. I’ve never paid for a subscription to a major streamer, and at this point, I don’t see why I ever would.”

Read the whole story
mrmarchant
17 hours ago
reply
Share this story
Delete

Chimera

1 Share

a physical-modeling voice synthesizer with sounds made from simulated airways; try the singing mode

#
Read the whole story
mrmarchant
18 hours ago
reply
Share this story
Delete

Terry Pratchett's Study

2 Shares

My comment on Terry Pratchett's Study — Hacker News.

Terry Pratchett once wrote about the concept of "horizontal wealth". Vertical wealth is where you spend money on rich people stuff - yachts and suchlike. Horizontal wealth is where you spend more money on the things you liked before you got rich: https://chibuikeani.blogspot.com/2017/02/the-price-of-happin...

But horizontal wealth means not letting your increased income dictate your tastes. You like books and now you have money? Buy more books! Change those catenary bookshelves for good hardwood ones! In my case, build a library extension to your office. And, of course, you buy what will be useful for that most wonderful of pursuits, blind research, which is research without direction for the sheer joy of it.

(Original source is his book A Slip of the Keyboard - this linked blog post quotes that bit.)

Tags: hacker-news, terry-pratchett

Read the whole story
mrmarchant
1 day ago
reply
Share this story
Delete

School Communications Are a Mess

1 Share

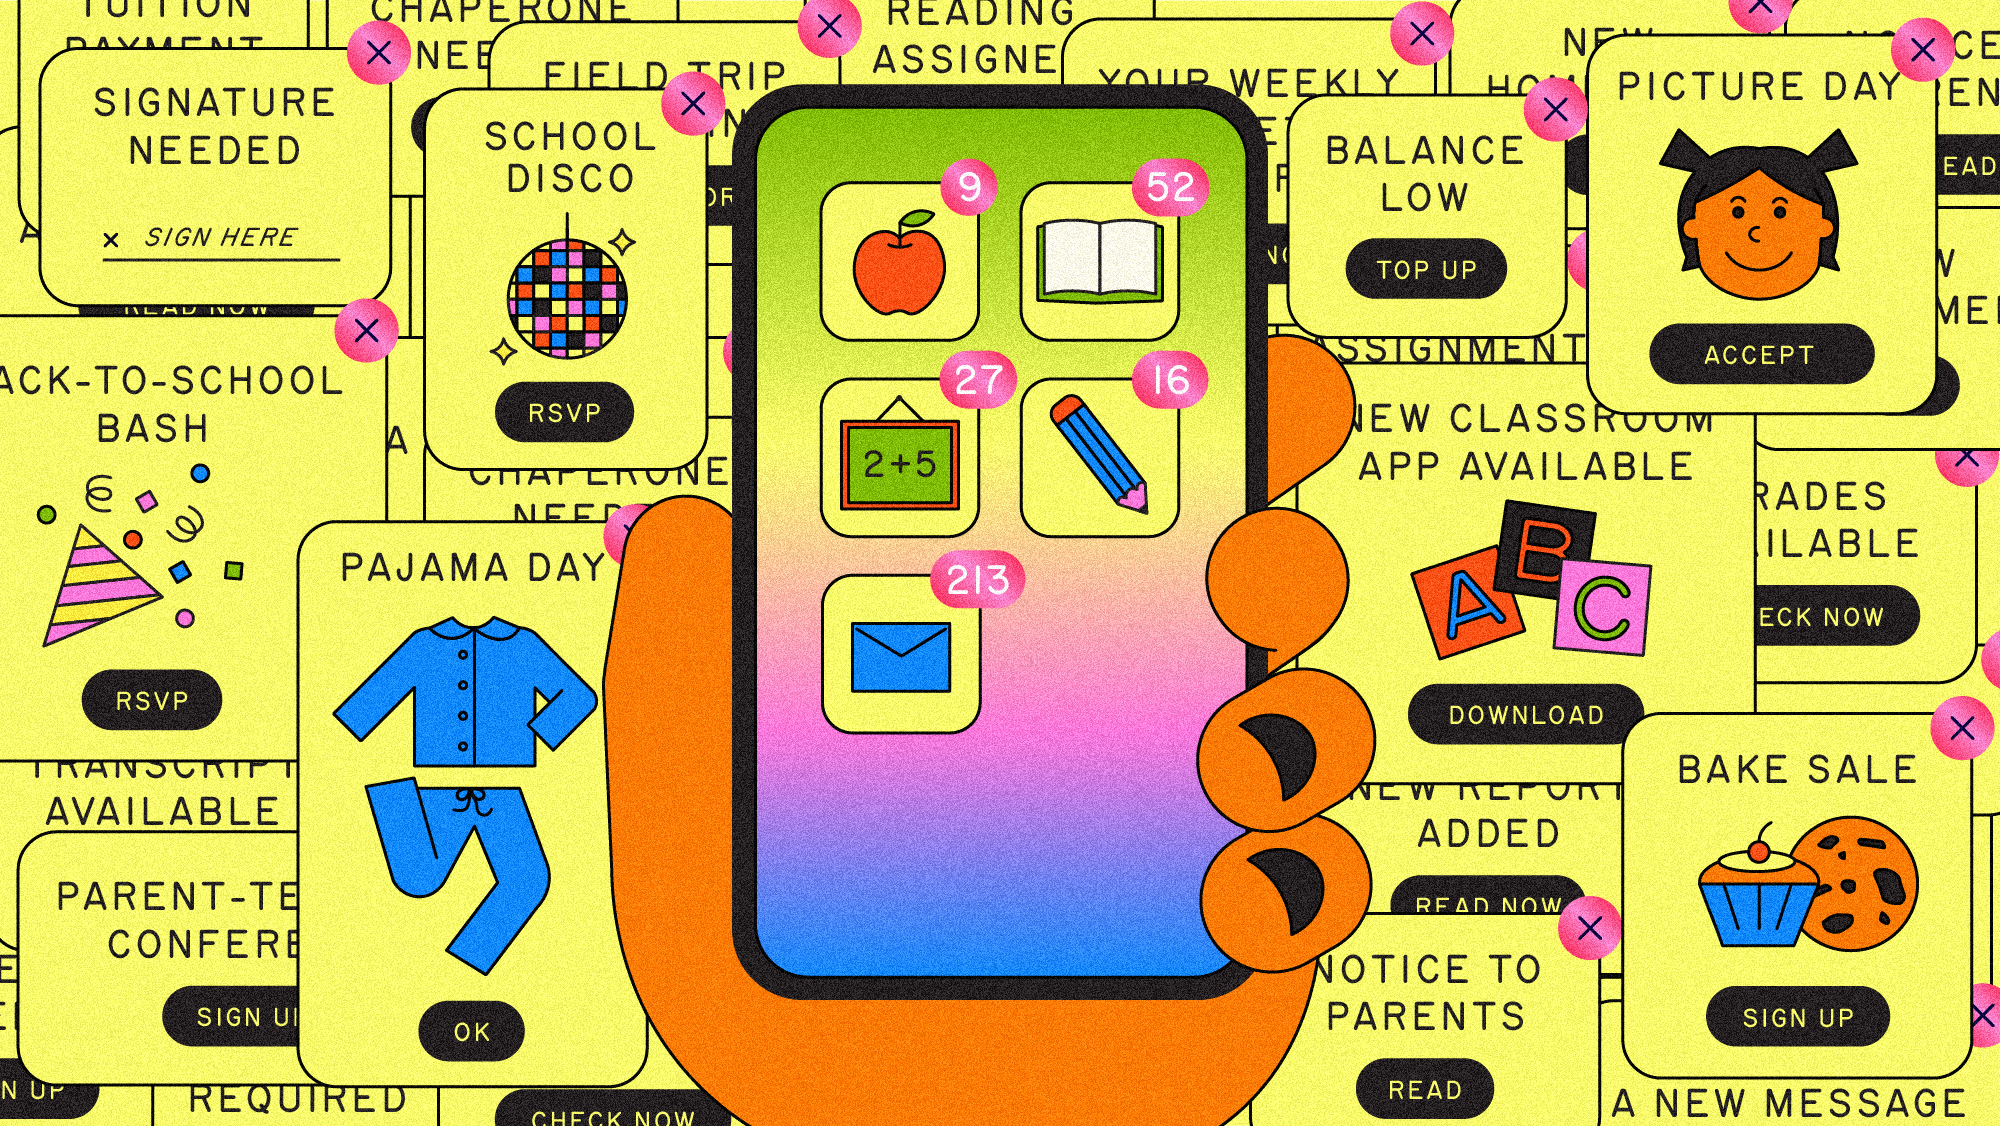
With the exception of my husband, no one contacts me as often as my children’s school does. There’s the old-school stuff: a folder that comes home in each of their backpacks weekly, filled with flyers and graded work and tests to sign; a binder with a nightly behavior and reading log, also for me to sign. I get texts and emails with the school’s weekly newsletter, updates from the PTA, and, more than anything else, notifications about posts on the various platforms and apps the school uses.

That brings me to the new-school stuff: ClassDojo for one kid. Bloomz for another (except for choir information, which is on ClassDojo). Something called PowerSchool, which is meant to be the district’s hub for grades but also—for some mysterious reason—sends me weekly automated emails telling me that the balance in my daughters’ accounts has fallen below $5. (This makes no sense. For one thing, their school lunch is free. For another, school payments are handled on another platform entirely.)

I’d like to think that, given the volume of information I receive, I have a solid grasp of how my children are faring in school. But I have reason to doubt as much. American parents are prone to overestimating how well their kids are doing in school. According to a recent report from Learning Heroes, a nonprofit whose aim is to help parents develop an accurate understanding of their children’s academic performance, about 88 percent of American parents say their child is performing at or above grade level in reading; 83 percent say the same about math. But in most states, the share of students meeting grade-level expectations in reading or math is less than 50 percent, according to the National Center for Education Statistics’ most recently available compilation of state scores.

This is the strange state of modern school communication: Although parents have access to an enormous amount of information about what their children are doing in school, many struggle to figure out whether their kids are actually keeping up. Having spent recent weeks chatting with parents and teachers in the hope of gaining better insight into where school-to-parent communication is breaking down, I’ve come to the conclusion that parents are receiving both too much and too little information at the same time.

[Read: A totally unnecessary way to stress parents out]

In my conversations with fellow parents about school messaging, communication overwhelm repeatedly came up. One parent in Rochester, New York, told me that her kids’ school seems to take a saturation approach, bombarding her with information via multiple tools, in hopes that her family will get the message. More than anything, parents complained that schools employ too many apps and online platforms. Joanna Cummings, a mother of four based in Indianapolis, told me that although all of her children go to the same school, she still has four different apps for communicating with teachers, plus a fifth site where certain test scores are posted.

When information is spread and frequently repeated across platforms, it’s hard to know where to look for updates—especially if there’s seemingly little rhyme or reason to what gets announced where. And the sheer volume of communications can make prioritizing difficult. “You have this undifferentiated fire hose of content coming at you from the school, but it’s not stratified in a useful way,” Matthias Schabel, a father of three in Portland, Oregon, told me. Often, important notices are tucked into messages that also contain a lot of fluff—a notification for Pajama Day, a reminder that Chuck E. Cheese is hosting a back-to-school night, an announcement that the district is holding a flower sale at the football game. The paradoxical outcome is that although the school might be sharing essential information with you, you can’t trust that you’ll see it.

Nancy Nayar, a mom of two in Brooklyn, told me that despite the numerous sources of information at her kids’ school—JumpRope and Jupiter for checking on grades and assignments; Google Classroom for daily content; a physical binder with written work; plus many, many papers sent home by folder—she was haunted by the possibility that she had a mistaken impression about her kids’ performance. “In some respects, you think, Well, I don’t have any excuse for not knowing everything that’s going on with my kids’ school,” Nayar said. “But there’s so much about every detail.”

Even streamlined information can be bewildering. Lindsay Meisel, a parent of two in San Francisco, told me that when her son was in first grade a couple of years ago, he fell behind in reading. Initially, she thought that his grades had revealed little reason to worry. Instead of giving traditional letter grades, the school uses a system that evaluates children on a scale from one to four—and when her son got mostly twos and threes, his teacher told her that was normal. When it seemed that her son hadn’t done well on a computer-adaptive test called a Star assessment, which is designed to track a child’s progression toward grade-level expectations, she said she was told to take those numbers with a grain of salt, because lots of younger kids struggle with online testing. That seemed reasonable to her.

Even so, this left Meisel confused about whether she needed to intervene. “The one objective measure that I feel like I can really trust, where he did poorly, you’re saying that actually is not reliable,” Meisel recalled thinking. “But then, what is reliable?” It took a third-party evaluation for Meisel to understand that her son was seriously behind.

This points to a troubling irony: For all of the frustration that parents have with overcommunication from schools, they may not be receiving—or clocking—some of the most crucial pieces of information. “If your kid is bringing home a good grade, you assume that that good grade means your child’s on grade level,” Bibb Hubbard, the founder of Learning Heroes, told me. “That’s inaccurate.”

Misunderstandings about grades are driven in part by rampant grade inflation. As Kelsey Piper recently documented in The Argument, the average GPA of American high schoolers rose from about 2.6 in 1987 to 3.1 in 2019—despite the fact that 12th-grade performance on standardized tests such as the National Assessment of Educational Progress was stagnant or even falling for much of that period. But grade inflation isn’t the only issue, Hubbard said. After all, grades take into consideration achievements other than mastery of material, including effort, engagement, and assignment completion. The trouble is that schools don’t always share a clear measure of grade-level performance, and even when they do, parents don’t necessarily know what to make of it. They rely on teachers to help them interpret their kids’ scores, but as Hubbard noted, “teachers are not trained or expected to tell parents the whole picture.”

[Jenny Anderson: What happened after a teacher ditched screens]

Meanwhile, many teachers have no choice but to spend their time spamming parents with mass updates. Abby Boruff, a public-school teacher in Des Moines, Iowa, told me that she thinks a lot of teachers would agree that the use of apps for communication is out of control. But that’s not always a problem they are well situated to solve. School tech systems are typically adopted piecemeal. And once they’re in place, they can be hard to remove. “Nobody wants to get rid of the old stuff,” Boruff said. “They want to try new stuff, but we never want to get rid of the stuff that we don’t need anymore.” Plus, individual schools and systems are responsible for communicating a lot of different things, Kristen McQuillan, a former public-school teacher and the executive director of Knowledge Matters, a nonprofit aimed at improving school curricula, told me. Many different parties—the state, the school district, the principal—have a hand in determining what schools ought to be communicating and when.

Different parents also have different preferred ways of receiving information. Catering to all of them necessarily requires duplicating communication. Even trickier is the reality that many parents don’t want to hear bad news about their kid, Boruff said. They can also be hard to reach—or it can be difficult to get them into the school for a sit-down conversation. Data back this up: The share of K–8 parents attending parent-teacher conferences has fallen from 77 percent in 2017 to 57 percent today, according to the most recent data from Learning Heroes. This reluctance or inability to meet in person makes it tough for teachers to convey news about a child falling behind. “If I’m concerned about something,” Boruff said, “that’s not a conversation I want to have on ParentSquare.”

This doesn’t mean that teachers should settle for an easy out. Sometimes, the job requires sharing bad news, and teachers must be willing to deliver it, just as parents must be willing to receive it. Building the mutual trust needed for these challenging conversations may not be something an app can solve. So parents looking for clarity about whether their children are on track may have to dig for it—not in the glut of emails they receive from their kid’s school, but by reaching out to the teacher directly, for a real conversation.


Read the whole story
mrmarchant
3 days ago
reply
Share this story
Delete

Quoting Nilay Patel

1 Share

The products aren't good enough to sell people on the costs.

You cannot tell people that you have to listen to the whine of a data center in their backyard for AI overviews and some of the most hilarious deep fake slop in history.

It's not worth it. It just isn't worth it to anyone. And agents aren't real and they might not be being used the way that anyone wants them to yet. All these companies are spending more than they're making on these products. Refrigerators holding blood storage in Europe are being hacked.

The costs are too high. The benefits are not real. And if you connect that to corruption, you're like, in order to impose these costs on me, these CEOs are in the White House shaking Trump's hand, renaming it to the Gulf of America, paying for this ballroom that we don't want. It's obvious crypto-corruption, and it's still slop.

The AI industry will not get out of it until they make better products. Until everyone can see without needing to be convinced, without needing an ad campaign, without any of this stuff that just using these products makes your life better.

— Nilay Patel, The Vergecast: Big Tech lost big in the 2026 election

Tags: nilay-patel, slop, ai, generative-ai, ai-ethics

Read the whole story
mrmarchant
3 days ago
reply
Share this story
Delete

From Linux to Wikipedia: How Volunteers Build the Internet

1 Share

Peer production is responsible for some of the most valuable online resources, challenging the authority of firms, markets, and government bureaucracies.

Source: Adobe Stock

In 1991, a Finnish graduate student in computer science named Linus Torvalds sent a brief announcement to an online discussion group, saying he had been working on parts of a new operating system in his spare time. Torvalds described his project as “just a hobby [that] won’t be big and professional” and insisted that it would be free to use, study, modify, and distribute. Torvalds was building a technically challenging piece of software called an operating system “kernel,” which handles the most basic functions related to communication between a computer’s hardware and software. Unlike past operating system projects, Torvalds invited feedback and contributions from anyone on the Internet.

Benjamin Mako Hill, Christian Pentzold, and Aaron Shaw coauthored “Peer Production,” from which this article is adapted.

With time, Torvalds’ kernel attracted other developers who worked with him to turn the hobby project into an established piece of software that the group called “Linux.” This team combined their new kernel with another Internet-based collaborative project, GNU, whose goal was to create a replacement for the UNIX operating system but which had not yet produced a usable kernel. The result was the GNU/Linux operating system.

More than 30 years later, GNU/Linux (or just “Linux,” as most people call it) runs on billions of computers worldwide and has become one of the most important pieces of software in history. Nearly all supercomputers, a large majority of Internet servers, a majority of smartphones, and a growing number of “embedded systems” in devices like televisions run some version of Linux. In all of these markets, Linux did not simply fill an empty niche. Rather, it displaced many proprietary server operating systems from major manufacturers at the time, including Sun Microsystems, HP, and IBM.

Linux’s success upended the prevailing wisdom about how to build software. In the 1980s and 1990s, most world-class software was written by large, hierarchically managed teams of developers within immense, multinational corporations such as AT&T and Microsoft. Software developers worked full time for these companies and were well paid. The companies retained vast legal teams who used restrictive copyright licenses, proprietary patents, and technological measures to ensure that none of the code their developers wrote could ever be used — or, in most cases, even seen — by anyone outside the firm.

Linux took nearly every aspect of this proprietary software development approach and threw it out the window. The Linux kernel and the GNU/Linux operating system were built by volunteers collaborating outside firms, without hierarchical management structures, without money as the primary incentive, and without the typical legal or technical arrangements to restrict access, adaptation, or reuse of the underlying source code. The vast majority of early Linux contributors only wrote small amounts of code. But despite this unusual production model, Linux’s high quality and growing market share were undeniable by the end of the 1990s.

Linux took nearly every aspect of proprietary software development and threw it out the window.

Since then, Linux has inspired millions of attempts to build knowledge goods in a similarly open and collaborative manner. The most famous is the free, collaboratively produced encyclopedia Wikipedia. Like Linux, Wikipedia began with an open call for volunteer contributions to “an encyclopedia that anyone can edit” in January 2001. Wikipedia includes about 68 million articles across more than 300 different language editions. In the English-language version alone, the articles were built from more than a billion distinct contributions, or “edits,” by more than 121 million user accounts and many millions of anonymous contributors. Nearly all of these edits are from volunteers. Today, Wikipedia is one of the most-visited websites in the world and the largest and most comprehensive encyclopedia in history by nearly every metric.

The collaborative production model that underlies Linux and Wikipedia has also been used thousands of times at a smaller scale.

For example, while preparing his syllabus for a class in 2011, a law professor named Andreas Fischer-Lescano stumbled upon dubious passages in the doctoral thesis of the German politician and then-Minister of Defense Karl-Theodor zu Guttenberg. Fischer-Lescano searched the Internet and discovered that they had been copied from other sources without credit. In February 2011, a Twitter user raised the issue and asked for help with a thorough analysis of zu Guttenberg’s dissertation. Many volunteers joined GuttenPlag Wiki — a participatory online platform created for that purpose — and within a couple of days, hundreds of pages of zu Guttenberg’s thesis were marked up with detailed documentation of apparent plagiarism in many places. About two weeks later, zu Guttenberg resigned from all political offices in light of the incriminating findings.


Although radically different in terms of size, scale, and scope, Linux, Wikipedia, and GuttenPlag Wiki are all examples of what you might call “commons-based peer production,” a term coined in the early 2000s by a law professor named Yochai Benkler.

Drawing on Benkler’s work, we propose a new definition of peer production. We hold that these projects must do four things:

  1. Motivate participants to contribute using diverse incentives that are frequently, if not exclusively, nonmonetary.
  2. Be decentralized in that they are collectively self-governed and organized by participants.
  3. Be decentralized in terms of how tasks are executed.
  4. Create content that is protected as part of the public commons.

Peer production projects may be similar to markets in that they rely on the distributed, self-directed actions of individuals to create information and other kinds of goods. However, unlike markets, peer production involves neither financial incentives nor prices nor exclusive property regimes. And unlike firms or government organizations, peer production involves neither contractual obligations, pre-defined work plans, nor hierarchical forms of management and task assignment. While some people may contribute to peer production as part of their job, many do so as volunteers. When people do engage in peer production as part of their jobs, employers usually do not dictate the type of peer production work they pursue.

It’s worth repeating that these characteristics defy conventional assumptions about organizations and economic production.

According to classical economic wisdom, if you want people to collaborate and efficiently distribute the outputs of that collaboration, the best way to do so is through private, for-profit firms that sell goods or services in an open market. Firms hire and pay employees who are then contractually bound to pursue the work assigned to them by managers. The products of the work these employees do become company property, which sets their price, manages sales transactions, and distributes salaries and any profits generated along the way.

In theory, these techniques address the challenges of aligning incentives, organizing tasks, and ensuring that the resulting outputs are distributed to those willing and able to pay for them.

But peer production represents an alternative to the behavioral models at the heart of classical economic wisdom. Neither contractual obligations, financial incentives, nor bureaucratic authority ensures that participants contribute their work or that the work is organized effectively. The resulting products are public commons protected as non-exclusive (rather than private) forms of intellectual property. This means that peer-produced resources cannot be priced directly on the open market.

In its Platonic ideal, peer production projects retain complete collective, autonomous control over the scope of their work, the legitimacy of their leaders’ authority, and the selection of tasks worth pursuing. In practice, though, peer production is often employed to varying degrees — by institutions that do not neatly check all the definitional boxes.

Peer production represents an alternative to the behavioral models at the heart of classical economic wisdom.

Take, for example, a site like Reddit. On Reddit, people join topically defined subcommunities, or subreddits, where they voluntarily share information in “posts,” then vote on and comment on those posts. The aggregation — also known as collaborative filtering — of the voting and commenting activity produces a collective sense of what’s most interesting or important. Thinking back to our definition above of peer production, we would say that Reddit relies on diverse nonmonetary motivations and decentralized goal-setting and execution, but the products have always been formally controlled by Reddit’s corporate owners (i.e., not a commons).

Reddit’s owners initially adopted a very permissive attitude toward data redistribution and reuse that made Reddit function like a commons. Over time, however, this changed as Reddit prepared for its initial public offering (IPO) in 2024. AI companies engaged in bulk collection and reuse of Reddit data, raising the financial stakes and introducing threats to the site’s viewership and engagement. In Spring 2023, Reddit’s owners restricted access to their data and began charging for it, making the site much less commons-like and provoking a backlash among some of the most committed volunteer contributors.

Online sites and services like Yelp and YouTube have similarly eroded the boundaries between markets and peer production. On these platforms, participants contribute content for free while others are compensated through advertising revenues, product placement, or access to private events. In cases like Airbnb, private companies profit from an activity (hosting guests through “couchsurfing”) that was previously managed in a non-monetized way by a peer-production community offering nearly identical services, such as Couchsurfing and Hospitality Club. Airbnb is not peer production, but it also seems unlikely that it could have existed without peer production to show it the way.


When you really think about peer production at its most basic level, you might ask: What is a bunch of unpaid volunteers doing at the heart of the modern commercial Internet? How do these volunteers get anything done if nobody is in charge and nobody pays them for their work? Why should we trust anything these communities create to support so many fundamental parts of our digital lives?

These are, fundamentally, some of the most core questions in the field.

After all, despite all the fanfare about “the wisdom of crowds,” collaborative production on the Internet remains both rare and challenging. For every example of a peer-produced product, there are many unsuccessful attempts to build a collaborative community. Many of these failed efforts to build communities produced valuable knowledge commons in their own right. For example, in a study of software commons, Charles Schweik and Robert English found that a large portion of successful software commons — nearly half — only involve a single developer writing code on their own and sharing it with the world. In other words, many software commons are entirely uncollaborative.

You might ask: How do these volunteers get anything done if nobody is in charge?

As peer production communities have matured, they have also encountered challenges and limitations. Broadly speaking, peer production has advanced most rapidly in the Global North and tends to reflect the demographic attributes and interests of the wealthiest and most digitally literate. Inside communities, hierarchies and power relations have emerged, and sexism and harassment can be widespread. Additionally, projects that grow tend to become more formalized, resulting in open communities that are, at the same time, highly structured, bureaucratic organizations. Even when communities welcome newcomers, arriving volunteers often meet multiple obstacles that effectively exclude all but the most highly educated and Internet-savvy individuals.

Nevertheless, peer production has continued to shape the world in both direct and indirect ways. As wikis, distributed software development, and related modes of online collaboration have become more widespread, they have influenced how more traditional organizations structure themselves. This includes the so-called “sharing economy,” crowdfunding, distributed computing, user-generated content production on commercial platforms such as YouTube and Yelp, hacking and fabrication spaces in the DIY movement, social media systems, and even blockchain-based technologies such as cryptocurrencies. Generative artificial intelligence systems and digital assistants, such as OpenAI’s ChatGPT, answer questions using data from peer-produced sources.

When Linux was released, not even its authors foresaw the emergence of peer production, nor could they have imagined that anyone would still be writing about their work decades later. But now, at a time when many of the world’s most powerful companies and governments struggle with misinformation, declining civic participation, and growing social divisions, peer production offers an alternative model for addressing these new challenges.


Benjamin Mako Hill is a social scientist and technologist; Christian Pentzold is Professor and Chair of Media and Communications in the Department of Communication and Media Studies at Leipzig University; and Aaron Shaw is Professor of Communication Studies and Sociology at Northwestern University. They coauthored “Peer Production,” from which this article is adapted.


Read the whole story
mrmarchant
4 days ago
reply
Share this story
Delete
Next Page of Stories