Terry Pratchett once wrote about the concept of "horizontal wealth". Vertical wealth is where you spend money on rich people stuff - yachts and suchlike. Horizontal wealth is where you spend more money on the things you liked before you got rich: https://chibuikeani.blogspot.com/2017/02/the-price-of-happin...
But horizontal wealth means not letting your increased income dictate your tastes. You like books and now you have money? Buy more books! Change those catenary bookshelves for good hardwood ones! In my case, build a library extension to your office. And, of course, you buy what will be useful for that most wonderful of pursuits, blind research, which is research without direction for the sheer joy of it.
(Original source is his book A Slip of the Keyboard - this linked blog post quotes that bit.)
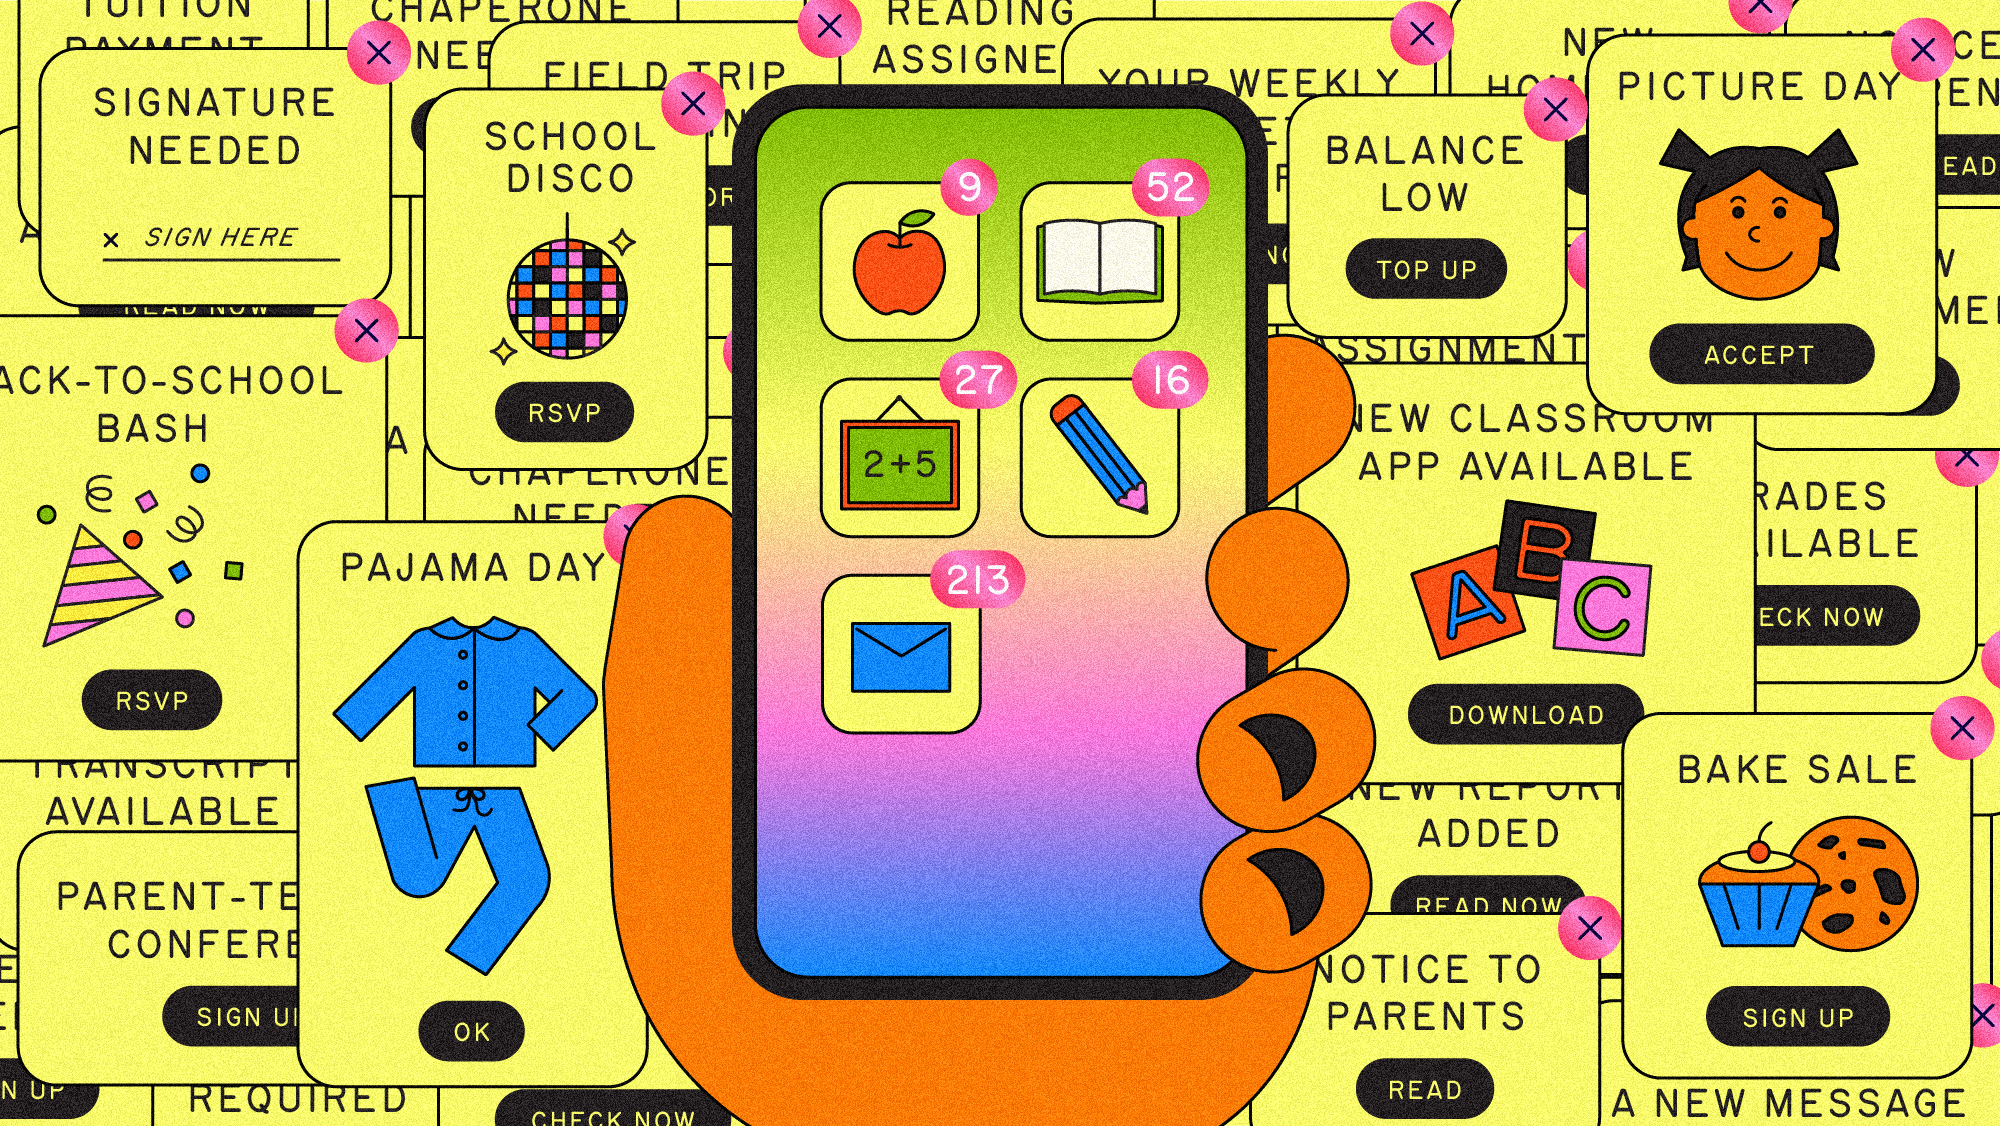
With the exception of my husband, no one contacts me as often as my children’s school does. There’s the old-school stuff: a folder that comes home in each of their backpacks weekly, filled with flyers and graded work and tests to sign; a binder with a nightly behavior and reading log, also for me to sign. I get texts and emails with the school’s weekly newsletter, updates from the PTA, and, more than anything else, notifications about posts on the various platforms and apps the school uses.
That brings me to the new-school stuff: ClassDojo for one kid. Bloomz for another (except for choir information, which is on ClassDojo). Something called PowerSchool, which is meant to be the district’s hub for grades but also—for some mysterious reason—sends me weekly automated emails telling me that the balance in my daughters’ accounts has fallen below $5. (This makes no sense. For one thing, their school lunch is free. For another, school payments are handled on another platform entirely.)
I’d like to think that, given the volume of information I receive, I have a solid grasp of how my children are faring in school. But I have reason to doubt as much. American parents are prone to overestimating how well their kids are doing in school. According to a recent report from Learning Heroes, a nonprofit whose aim is to help parents develop an accurate understanding of their children’s academic performance, about 88 percent of American parents say their child is performing at or above grade level in reading; 83 percent say the same about math. But in most states, the share of students meeting grade-level expectations in reading or math is less than 50 percent, according to the National Center for Education Statistics’ most recently available compilation of state scores.
This is the strange state of modern school communication: Although parents have access to an enormous amount of information about what their children are doing in school, many struggle to figure out whether their kids are actually keeping up. Having spent recent weeks chatting with parents and teachers in the hope of gaining better insight into where school-to-parent communication is breaking down, I’ve come to the conclusion that parents are receiving both too much and too little information at the same time.
In my conversations with fellow parents about school messaging, communication overwhelm repeatedly came up. One parent in Rochester, New York, told me that her kids’ school seems to take a saturation approach, bombarding her with information via multiple tools, in hopes that her family will get the message. More than anything, parents complained that schools employ too many apps and online platforms. Joanna Cummings, a mother of four based in Indianapolis, told me that although all of her children go to the same school, she still has four different apps for communicating with teachers, plus a fifth site where certain test scores are posted.
When information is spread and frequently repeated across platforms, it’s hard to know where to look for updates—especially if there’s seemingly little rhyme or reason to what gets announced where. And the sheer volume of communications can make prioritizing difficult. “You have this undifferentiated fire hose of content coming at you from the school, but it’s not stratified in a useful way,” Matthias Schabel, a father of three in Portland, Oregon, told me. Often, important notices are tucked into messages that also contain a lot of fluff—a notification for Pajama Day, a reminder that Chuck E. Cheese is hosting a back-to-school night, an announcement that the district is holding a flower sale at the football game. The paradoxical outcome is that although the school might be sharing essential information with you, you can’t trust that you’ll see it.
Nancy Nayar, a mom of two in Brooklyn, told me that despite the numerous sources of information at her kids’ school—JumpRope and Jupiter for checking on grades and assignments; Google Classroom for daily content; a physical binder with written work; plus many, many papers sent home by folder—she was haunted by the possibility that she had a mistaken impression about her kids’ performance. “In some respects, you think, Well, I don’t have any excuse for not knowing everything that’s going on with my kids’ school,” Nayar said. “But there’s so much about every detail.”
Even streamlined information can be bewildering. Lindsay Meisel, a parent of two in San Francisco, told me that when her son was in first grade a couple of years ago, he fell behind in reading. Initially, she thought that his grades had revealed little reason to worry. Instead of giving traditional letter grades, the school uses a system that evaluates children on a scale from one to four—and when her son got mostly twos and threes, his teacher told her that was normal. When it seemed that her son hadn’t done well on a computer-adaptive test called a Star assessment, which is designed to track a child’s progression toward grade-level expectations, she said she was told to take those numbers with a grain of salt, because lots of younger kids struggle with online testing. That seemed reasonable to her.
Even so, this left Meisel confused about whether she needed to intervene. “The one objective measure that I feel like I can really trust, where he did poorly, you’re saying that actually is not reliable,” Meisel recalled thinking. “But then, what is reliable?” It took a third-party evaluation for Meisel to understand that her son was seriously behind.
This points to a troubling irony: For all of the frustration that parents have with overcommunication from schools, they may not be receiving—or clocking—some of the most crucial pieces of information. “If your kid is bringing home a good grade, you assume that that good grade means your child’s on grade level,” Bibb Hubbard, the founder of Learning Heroes, told me. “That’s inaccurate.”
Misunderstandings about grades are driven in part by rampant grade inflation. As Kelsey Piper recently documented in The Argument, the average GPA of American high schoolers rose from about 2.6 in 1987 to 3.1 in 2019—despite the fact that 12th-grade performance on standardized tests such as the National Assessment of Educational Progress was stagnant or even falling for much of that period. But grade inflation isn’t the only issue, Hubbard said. After all, grades take into consideration achievements other than mastery of material, including effort, engagement, and assignment completion. The trouble is that schools don’t always share a clear measure of grade-level performance, and even when they do, parents don’t necessarily know what to make of it. They rely on teachers to help them interpret their kids’ scores, but as Hubbard noted, “teachers are not trained or expected to tell parents the whole picture.”
Meanwhile, many teachers have no choice but to spend their time spamming parents with mass updates. Abby Boruff, a public-school teacher in Des Moines, Iowa, told me that she thinks a lot of teachers would agree that the use of apps for communication is out of control. But that’s not always a problem they are well situated to solve. School tech systems are typically adopted piecemeal. And once they’re in place, they can be hard to remove. “Nobody wants to get rid of the old stuff,” Boruff said. “They want to try new stuff, but we never want to get rid of the stuff that we don’t need anymore.” Plus, individual schools and systems are responsible for communicating a lot of different things, Kristen McQuillan, a former public-school teacher and the executive director of Knowledge Matters, a nonprofit aimed at improving school curricula, told me. Many different parties—the state, the school district, the principal—have a hand in determining what schools ought to be communicating and when.
Different parents also have different preferred ways of receiving information. Catering to all of them necessarily requires duplicating communication. Even trickier is the reality that many parents don’t want to hear bad news about their kid, Boruff said. They can also be hard to reach—or it can be difficult to get them into the school for a sit-down conversation. Data back this up: The share of K–8 parents attending parent-teacher conferences has fallen from 77 percent in 2017 to 57 percent today, according to the most recent data from Learning Heroes. This reluctance or inability to meet in person makes it tough for teachers to convey news about a child falling behind. “If I’m concerned about something,” Boruff said, “that’s not a conversation I want to have on ParentSquare.”
This doesn’t mean that teachers should settle for an easy out. Sometimes, the job requires sharing bad news, and teachers must be willing to deliver it, just as parents must be willing to receive it. Building the mutual trust needed for these challenging conversations may not be something an app can solve. So parents looking for clarity about whether their children are on track may have to dig for it—not in the glut of emails they receive from their kid’s school, but by reaching out to the teacher directly, for a real conversation.
The products aren't good enough to sell people on the costs.
You cannot tell people that you have to listen to the whine of a data center in their backyard for AI overviews and some of the most hilarious deep fake slop in history.
It's not worth it. It just isn't worth it to anyone. And agents aren't real and they might not be being used the way that anyone wants them to yet. All these companies are spending more than they're making on these products. Refrigerators holding blood storage in Europe are being hacked.
The costs are too high. The benefits are not real. And if you connect that to corruption, you're like, in order to impose these costs on me, these CEOs are in the White House shaking Trump's hand, renaming it to the Gulf of America, paying for this ballroom that we don't want. It's obvious crypto-corruption, and it's still slop.
The AI industry will not get out of it until they make better products. Until everyone can see without needing to be convinced, without needing an ad campaign, without any of this stuff that just using these products makes your life better.
— Nilay Patel, The Vergecast: Big Tech lost big in the 2026 election
Peer production is responsible for some of the most valuable online resources, challenging the authority of firms, markets, and government bureaucracies.
Source: Adobe Stock
In 1991, a Finnish graduate student in computer science named Linus Torvalds sent a brief announcement to an online discussion group, saying he had been working on parts of a new operating system in his spare time. Torvalds described his project as “just a hobby [that] won’t be big and professional” and insisted that it would be free to use, study, modify, and distribute. Torvalds was building a technically challenging piece of software called an operating system “kernel,” which handles the most basic functions related to communication between a computer’s hardware and software. Unlike past operating system projects, Torvalds invited feedback and contributions from anyone on the Internet.
Benjamin Mako Hill, Christian Pentzold, and Aaron Shaw coauthored “Peer Production,” from which this article is adapted.
With time, Torvalds’ kernel attracted other developers who worked with him to turn the hobby project into an established piece of software that the group called “Linux.” This team combined their new kernel with another Internet-based collaborative project, GNU, whose goal was to create a replacement for the UNIX operating system but which had not yet produced a usable kernel. The result was the GNU/Linux operating system.
More than 30 years later, GNU/Linux (or just “Linux,” as most people call it) runs on billions of computers worldwide and has become one of the most important pieces of software in history. Nearly all supercomputers, a large majority of Internet servers, a majority of smartphones, and a growing number of “embedded systems” in devices like televisions run some version of Linux. In all of these markets, Linux did not simply fill an empty niche. Rather, it displaced many proprietary server operating systems from major manufacturers at the time, including Sun Microsystems, HP, and IBM.
Linux’s success upended the prevailing wisdom about how to build software. In the 1980s and 1990s, most world-class software was written by large, hierarchically managed teams of developers within immense, multinational corporations such as AT&T and Microsoft. Software developers worked full time for these companies and were well paid. The companies retained vast legal teams who used restrictive copyright licenses, proprietary patents, and technological measures to ensure that none of the code their developers wrote could ever be used — or, in most cases, even seen — by anyone outside the firm.
Linux took nearly every aspect of this proprietary software development approach and threw it out the window. The Linux kernel and the GNU/Linux operating system were built by volunteers collaborating outside firms, without hierarchical management structures, without money as the primary incentive, and without the typical legal or technical arrangements to restrict access, adaptation, or reuse of the underlying source code. The vast majority of early Linux contributors only wrote small amounts of code. But despite this unusual production model, Linux’s high quality and growing market share were undeniable by the end of the 1990s.
Linux took nearly every aspect of proprietary software development and threw it out the window.
Since then, Linux has inspired millions of attempts to build knowledge goods in a similarly open and collaborative manner. The most famous is the free, collaboratively produced encyclopedia Wikipedia. Like Linux, Wikipedia began with an open call for volunteer contributions to “an encyclopedia that anyone can edit” in January 2001. Wikipedia includes about 68 million articles across more than 300 different language editions. In the English-language version alone, the articles were built from more than a billion distinct contributions, or “edits,” by more than 121 million user accounts and many millions of anonymous contributors. Nearly all of these edits are from volunteers. Today, Wikipedia is one of the most-visited websites in the world and the largest and most comprehensive encyclopedia in history by nearly every metric.
The collaborative production model that underlies Linux and Wikipedia has also been used thousands of times at a smaller scale.
For example, while preparing his syllabus for a class in 2011, a law professor named Andreas Fischer-Lescano stumbled upon dubious passages in the doctoral thesis of the German politician and then-Minister of Defense Karl-Theodor zu Guttenberg. Fischer-Lescano searched the Internet and discovered that they had been copied from other sources without credit. In February 2011, a Twitter user raised the issue and asked for help with a thorough analysis of zu Guttenberg’s dissertation. Many volunteers joined GuttenPlag Wiki — a participatory online platform created for that purpose — and within a couple of days, hundreds of pages of zu Guttenberg’s thesis were marked up with detailed documentation of apparent plagiarism in many places. About two weeks later, zu Guttenberg resigned from all political offices in light of the incriminating findings.
Although radically different in terms of size, scale, and scope, Linux, Wikipedia, and GuttenPlag Wiki are all examples of what you might call “commons-based peer production,” a term coined in the early 2000s by a law professor named Yochai Benkler.
Drawing on Benkler’s work, we propose a new definition of peer production. We hold that these projects must do four things:
Motivate participants to contribute using diverse incentives that are frequently, if not exclusively, nonmonetary.
Be decentralized in that they are collectively self-governed and organized by participants.
Be decentralized in terms of how tasks are executed.
Create content that is protected as part of the public commons.
Peer production projects may be similar to markets in that they rely on the distributed, self-directed actions of individuals to create information and other kinds of goods. However, unlike markets, peer production involves neither financial incentives nor prices nor exclusive property regimes. And unlike firms or government organizations, peer production involves neither contractual obligations, pre-defined work plans, nor hierarchical forms of management and task assignment. While some people may contribute to peer production as part of their job, many do so as volunteers. When people do engage in peer production as part of their jobs, employers usually do not dictate the type of peer production work they pursue.
It’s worth repeating that these characteristics defy conventional assumptions about organizations and economic production.
According to classical economic wisdom, if you want people to collaborate and efficiently distribute the outputs of that collaboration, the best way to do so is through private, for-profit firms that sell goods or services in an open market. Firms hire and pay employees who are then contractually bound to pursue the work assigned to them by managers. The products of the work these employees do become company property, which sets their price, manages sales transactions, and distributes salaries and any profits generated along the way.
In theory, these techniques address the challenges of aligning incentives, organizing tasks, and ensuring that the resulting outputs are distributed to those willing and able to pay for them.
But peer production represents an alternative to the behavioral models at the heart of classical economic wisdom. Neither contractual obligations, financial incentives, nor bureaucratic authority ensures that participants contribute their work or that the work is organized effectively. The resulting products are public commons protected as non-exclusive (rather than private) forms of intellectual property. This means that peer-produced resources cannot be priced directly on the open market.
In its Platonic ideal, peer production projects retain complete collective, autonomous control over the scope of their work, the legitimacy of their leaders’ authority, and the selection of tasks worth pursuing. In practice, though, peer production is often employed to varying degrees — by institutions that do not neatly check all the definitional boxes.
Peer production represents an alternative to the behavioral models at the heart of classical economic wisdom.
Take, for example, a site like Reddit. On Reddit, people join topically defined subcommunities, or subreddits, where they voluntarily share information in “posts,” then vote on and comment on those posts. The aggregation — also known as collaborative filtering — of the voting and commenting activity produces a collective sense of what’s most interesting or important. Thinking back to our definition above of peer production, we would say that Reddit relies on diverse nonmonetary motivations and decentralized goal-setting and execution, but the products have always been formally controlled by Reddit’s corporate owners (i.e., not a commons).
Reddit’s owners initially adopted a very permissive attitude toward data redistribution and reuse that made Reddit function like a commons. Over time, however, this changed as Reddit prepared for its initial public offering (IPO) in 2024. AI companies engaged in bulk collection and reuse of Reddit data, raising the financial stakes and introducing threats to the site’s viewership and engagement. In Spring 2023, Reddit’s owners restricted access to their data and began charging for it, making the site much less commons-like and provoking a backlash among some of the most committed volunteer contributors.
Online sites and services like Yelp and YouTube have similarly eroded the boundaries between markets and peer production. On these platforms, participants contribute content for free while others are compensated through advertising revenues, product placement, or access to private events. In cases like Airbnb, private companies profit from an activity (hosting guests through “couchsurfing”) that was previously managed in a non-monetized way by a peer-production community offering nearly identical services, such as Couchsurfing and Hospitality Club. Airbnb is not peer production, but it also seems unlikely that it could have existed without peer production to show it the way.
When you really think about peer production at its most basic level, you might ask: What is a bunch of unpaid volunteers doing at the heart of the modern commercial Internet? How do these volunteers get anything done if nobody is in charge and nobody pays them for their work? Why should we trust anything these communities create to support so many fundamental parts of our digital lives?
These are, fundamentally, some of the most core questions in the field.
After all, despite all the fanfare about “the wisdom of crowds,” collaborative production on the Internet remains both rare and challenging. For every example of a peer-produced product, there are many unsuccessful attempts to build a collaborative community. Many of these failed efforts to build communities produced valuable knowledge commons in their own right. For example, in a study of software commons, Charles Schweik and Robert English found that a large portion of successful software commons — nearly half — only involve a single developer writing code on their own and sharing it with the world. In other words, many software commons are entirely uncollaborative.
You might ask: How do these volunteers get anything done if nobody is in charge?
As peer production communities have matured, they have also encountered challenges and limitations. Broadly speaking, peer production has advanced most rapidly in the Global North and tends to reflect the demographic attributes and interests of the wealthiest and most digitally literate. Inside communities, hierarchies and power relations have emerged, and sexism and harassment can be widespread. Additionally, projects that grow tend to become more formalized, resulting in open communities that are, at the same time, highly structured, bureaucratic organizations. Even when communities welcome newcomers, arriving volunteers often meet multiple obstacles that effectively exclude all but the most highly educated and Internet-savvy individuals.
Nevertheless, peer production has continued to shape the world in both direct and indirect ways. As wikis, distributed software development, and related modes of online collaboration have become more widespread, they have influenced how more traditional organizations structure themselves. This includes the so-called “sharing economy,” crowdfunding, distributed computing, user-generated content production on commercial platforms such as YouTube and Yelp, hacking and fabrication spaces in the DIY movement, social media systems, and even blockchain-based technologies such as cryptocurrencies. Generative artificial intelligence systems and digital assistants, such as OpenAI’s ChatGPT, answer questions using data from peer-produced sources.
When Linux was released, not even its authors foresaw the emergence of peer production, nor could they have imagined that anyone would still be writing about their work decades later. But now, at a time when many of the world’s most powerful companies and governments struggle with misinformation, declining civic participation, and growing social divisions, peer production offers an alternative model for addressing these new challenges.
Benjamin Mako Hill is a social scientist and technologist; Christian Pentzold is Professor and Chair of Media and Communications in the Department of Communication and Media Studies at Leipzig University; and Aaron Shaw is Professor of Communication Studies and Sociology at Northwestern University. They coauthored “Peer Production,” from which this article is adapted.
 Log in