Log in


When I first started writing for the internet, I learned very quickly that paragraphs here work very differently than they do in books.
Paragraphs in books tend to follow the rules we learned in school: they should be about a single topic, they should begin with a sentence introducing the topic, and the sentences that follow should develop the argument about that topic, until you’re finally ready to talk about something else.
“How long should a paragraph be?” I remember asking my high school English teacher.
“As long as it has to be,” came the response.
And in that moment the student was enlightened.
Enlightened enough, at least, to get through my five-paragraph high school essays, my maybe-thirty-paragraph term papers in university, all the way to my (too-many-paragraphs-to-count) dissertation in grad school.
So, when I first started writing for the internet, I tried writing in the same way I had been trained to all those years ago. Much to my dismay, I found that readers were not as enthusiastic about the paragraphs that my English teachers had taught me to love.
As you can see from the paragraphing of this very article, I did eventually come to embrace a more internet-native way of writing. Now, much to the delight of my editor, I hit the “Enter” button with gleeful abandon, even if it pains a small part of me to do so.
However, as I’ve started once again to write material destined to be printed on paper, the ghost of the traditional single-topic paragraph has come back to haunt me, and I’ve had to unlearn some of the habits I’ve worked so hard to inculcate for online writing.
All this put some questions in my mind: Where do our ideas about paragraphs come from? And why does the internet-native paragraph work so differently from its traditional cousin?
As is so often the case, the answer begins in Ancient Greece.
You’re reading The Dead Language Society, where 91,000+ readers explore the hidden history of the English language. I’m Colin Gorrie: PhD linguist and your guide through 1,500 years of linguistic history.
I publish every Wednesday. Paid subscribers get every issue, the full archive, and my most in-depth work, including longer essays that trace the mysteries of English to their source, practical guides to reading historical texts yourself, and live book clubs where we read texts like Beowulf and Sir Gawain and the Green Knight.
Pilcrows and rubricators
The paragraph is not found in nature.
It is a human invention, one which began as a horizontal stroke written at the beginning of a line of text, extending under the first few letters.
The literal meaning of Ancient Greek parágraphos is ‘written beside’, which is an apt description. Sometimes the parágraphos was adorned in some way, either with a dot or circle, or else forked at one end, as in the following example:
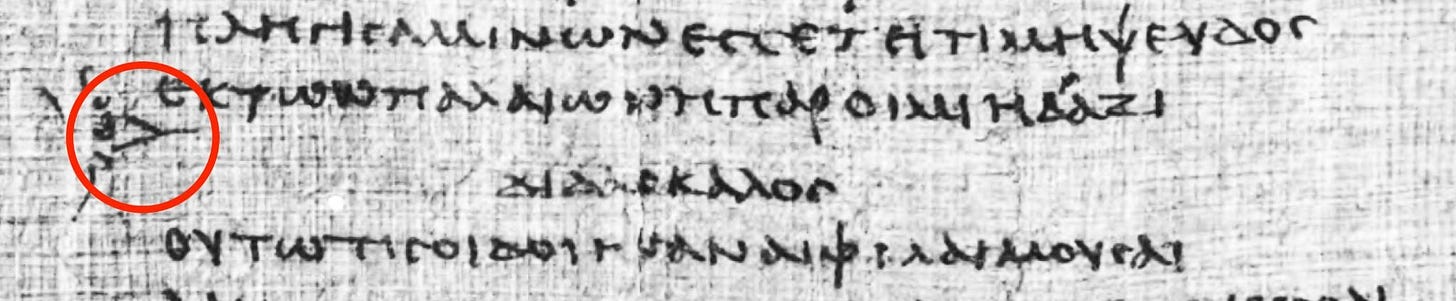
The parágraphos was used to signal the end of a section, such as a chapter of a longer text, or the end of one speaker’s dialogue in a drama.1
Later medieval scribes inherited the convention of writing something beside the text to indicate a break of some sort. For this they used the letter C, which stood for the Latin word capitulum, literally ‘little head’.
Capitulum is also the source of the English word chapter, which refers to a section of text as well, albeit a rather larger one.2
The C of the medieval scribes later acquired a line drawn through it, and eventually, through a convoluted sequence of forms and uses, this assemblage evolved into ¶, the “new paragraph” symbol used by proofreaders to this day, at least when they’re working by hand. This symbol has a name too, which shows up from time to time in crosswords and the like: pilcrow, a term distantly related to paragraph.3
These new-paragraph marks were not written along with the rest of the text. Instead, they were added later, in red ink, by a separate scribe called a rubricator — so named because he wrote in ruber, the Latin for ‘red’.4
Early printers inherited these customs. When they came to the beginning of a new paragraph, they left a space for the rubricator to add the ¶ symbol. Unfortunately for the rubricator’s job security, the existence of the blank space to mark a new paragraph made the ¶ redundant — and, since hand rubrication was expensive, the blank was often left unfilled.
This blank is the origin of the modern practice of using indentation to begin paragraphs. At first, to save space, a new paragraph would often begin on the same line as the previous one. Only in 1499 did Aldus Manutius (a friend of the Dead Language Society) first start marking paragraphs consistently with a blank space and a line break.5
That’s how paragraphs came to look like they do today. But how did they come to mean what they do today — and why does that meaning differ between page and screen?
The rise of the paragraph
The ancient Greek parágraphos didn’t correspond to any particular division of a text: it marked the end of something, which could be the portion of a play spoken by one character, an item in a list, or even just a single sentence.6
But there were ideas in ancient Greek thought about how to divide a text into parts. The division closest to the modern idea of a paragraph is the rhetorical unit called the period.
Technically, however, the ancient period corresponds to a modern sentence — and indeed gives its name, in some English dialects, to the bit of punctuation that ends a modern sentence — but the periods favoured by ancient writers were much longer than modern sentences.7
The period has its origins in ancient rhetoric — representing a group of prose that ends with a break for breathing. For Aristotle, the period should be bounded conceptually by how much material a reader or listener could hold in mind without needing a break:
By a period I mean a portion of speech that has in itself a beginning and an end, being at the same time not too big to be taken in at a glance. (Aristotle, Rhetoric 3.9, 1409a–b; trans. W. Rhys Roberts).
But the theorizing about the rhetorical divisions of a text occurred parallel to the development of signs to mark the divisions of a text. It took the print revolution to connect the two.
In particular, writers of practical texts — as opposed to literary ones — used the visual separation of the paragraph to match the conceptual division between, say, steps in an operation. This was already happening in the 15th century, the earliest days of print.8
Another factor behind the rise of the paragraph as a meaningful division of a text was the decline in the length of sentences. The longer, Latinate sentences popular in the English Renaissance grew gradually shorter over the centuries, as the reading public came to be composed more and more of the middle classes.9
Middle-class readers lacked the taste for the periodic style of sentence favoured by those with a Latin education. As sentences grew shorter, the ideas in sentences needed to be connected more explicitly. The paragraph was the perfect tool for the job.10
Even so, it wasn’t until the nineteenth century that an explicit ideology arose surrounding what the paragraph should mean. The most popular and influential expression of this ideology came from the Scottish philosopher Alexander Bain, who devised a set of rules for writing paragraphs.
There were six such rules, which he introduced in his 1866 textbook English Composition and Rhetoric. Here they are, in a modernized form:11
Explicit reference. Within a paragraph, it should be obvious how each sentence relates to the previous one.
Parallel construction. Sentences expressing similar ideas should have similar structures.
Topic sentence. The first sentence should introduce what the paragraph is about, although Bain allows the occasional preparatory sentence to precede it.
Consecutive arrangement. Each sentence in the paragraph should be in its logical position given what the paragraph is trying to do.
Overall unity. The paragraph should be about one single topic and should not feature digressions.
Subordination. The amount of space devoted to each aspect of a topic should be in proportion to its importance. Don’t spend too many words on minor matters.
Taken together, Bain’s six rules imply that paragraphs must have a particular shape. They must begin with a sentence informing us what they are about, and they must proceed in a logical fashion until the author has exhausted what there is to say about the topic.
You may recognize this theory of paragraph construction from high school English class. I certainly do. But it is very different from how almost everyone actually writes, at least on the internet.
When writing on the internet, I find myself operating by a theory of the paragraph that goes something like this: start a new paragraph when the current paragraph is getting “too long”.
What constitutes “too long”? There doesn’t seem to be any strict rule, but I find I end up pressing “Enter, Enter” every 30–50 words when writing for the internet.
My editor is stricter still: between my first draft of an article and the one you end up reading, dozens of new paragraph breaks have come into being. (Editor’s note: only 5 new paragraph breaks have come into being!)
How far we have fallen from Bain’s six rules!
As it turns out, however, this hyper-paragraph-osis isn’t just an internet thing.
We are all journalists now
Short paragraphs were originally a journalism thing — at least, a thing journalism promoted, dating back to the 20th century and beyond.12
As Willard Grosvenor Bleyer wrote in Newspaper Writing and Editing, an influential journalism textbook from 1913,
One of the distinctive peculiarities of newspaper style is the brevity of the paragraph. The width of newspaper columns permits about seven words in a line. The result is that a paragraph of the length usual in prose style generally, i.e., from 150 to 250 words, would occupy from 20 to 35 lines and would appear disproportionately long for its width. Paragraphs that are long, or appear to be so, make a piece of writing look solid and heavy, hence uninviting to the rapid reader. In newspaper work, accordingly, it has come to be recognized that shorter paragraphs are more effective. Paragraphs of from 50 to 150 words are considered the normal type for newspaper writing.13
As a consequence, Bleyer continues, “what would be subdivisions, each with a sub-topic, in the common type of longer paragraphs, become independent paragraphs in newspaper style.”14 As a result, the unit corresponding to Bain’s unitary paragraph is, in journalism, a group of adjacent paragraphs.
This is more or less the house style of the internet.15 The innovation of the screen was to make the old journalistic convention a “default setting” across genres.16 The feeling of heaviness that attended reading the seven-word lines of newspaper columns seems to be inherent to any kind of reading on screens.
Today, however, print journalism is often given more space to breathe than the old columns had. As a result, the paragraphing in newspapers and magazines is often less aggressive than the custom Breyer described. When news organizations run the same article in print and online editions, the print version is often paragraphed much less aggressively.17
Despite what your English teacher may once have told you, the paragraph doesn’t have any sacred or immutable meaning. It is there to serve the needs of the reader of the text.
These needs depend on the genre of the text as well as the physical details of how the text is delivered. The result is that ideal paragraph length can be very different depending on what you’re reading — and where you’re reading it.
To give a personal example from this very Substack, the denser and more technical the topic, the more aggressively the article is paragraphed.
My editor and I are humbly adapting Aristotle’s principle: the paragraphs shrink so that they’re never too big to be taken in at a glance. It’s just that reading on electronic devices — or reading about technical topics — brings us to “too big” remarkably quickly, often after only two or three sentences.
What do you think? Do you approve of these shorter, internet paragraphs? Or should we all be pressing “Enter” much less often?
Works cited
Aristotle (1924). Rhetoric. Translated by W. Rhys Roberts.
Bleyer, Willard Grosvenor (1913). Newspaper Writing and Editing.
Harris, Neil (2020). Costs We Don’t Think About: An Unusual Copy of Franciscus de Platea, Opus restitutionum (1474), and a Few Other Items. In Cristina Dondi (ed.), Printing R-Evolution and Society 1450–1500: Fifty Years that Changed Europe, 511–540.
Johnson, William A. (1994). The Function of the Paragraphus in Greek Literary Prose Texts. Zeitschrift für Papyrologie und Epigraphik 100: 65–68.
Oxford English Dictionary (OED), online edition, s.vv. full stop, period, pilcrow, rubric.
Robotham, Andrew T. & Nathalie Pignard-Cheynel (2024). You Said Digital First! A Five-Dimensional Definition According to Journalists from Three Swiss Newspapers. Journalism Practice 18(7): 1702–1721. Published online in 2022.
Shearer, Ned A. (1972). Alexander Bain and the Genesis of Paragraph Theory. Quarterly Journal of Speech 58(4): 408–417.
Tebeaux, Elizabeth (2011). Technical Writing and the Development of the English Paragraph 1473–1700. Journal of Technical Writing and Communication 41(3): 219–253.
Johnson (1994: 65).
Parkes (1993: 43–44).
So says the OED, although both halves of the word have been changed rather radically (OED, s.v. pilcrow.).
This is also where the word rubric comes from. Rubric meant first an instruction for conducting a church service — also, by convention, written in red ink — and only later became a more general word for a custom or standard (OED, s.v. rubric).
Harris (2020: 519).
Johnson (1994: 65).
The punctuation mark called a period in North American English is called a full stop everywhere else. For what it’s worth, period is attested earlier (1582) than full stop (1643) in this usage, but I’m not sure where the division between North America and the rest of the English-speaking world comes from (OED, s.vv. period, full stop.).
Tebeaux (2011).
Lewis (1894: 34–37, 170–171).
Tebeaux (2004, 2011).
Following the naming in Shearer (1972: 413).
Lewis (1894: 49).
Bleyer (1913: 64).
Bleyer (1913: 64).
Kehoe and Gee (2007: §7.1.2).
Bleyer’s 50–150 word-paragraphs strike me as a little lengthy for most internet writing.
Robotham and Pignard-Cheynel (2022/2024: 1710).