2069 stories
·
3 followers

Why the Internet Needs a Memory

1 Share

In 1996, during the early years of the web, I could see that those of us who were participating online were creating an extraordinary new record of human activity—and allowing it to disappear almost as quickly as we made it.

The web was becoming the place where government officials made promises, journalists published information in the public interest, and ordinary people shared ideas and documented their lives. Yet it was fragile—equal parts consequential and ephemeral.

Many people assume that once something is published online, it will remain forever retrievable. The saying that “the internet never forgets” has produced a dangerously false sense of permanence. In reality, the internet forgets continuously. Websites are constantly revised, deleted, and abandoned altogether.

This is why, 30 years ago, I founded the Internet Archive. I wanted to build a mechanism for permanence in the internet age. Soon after that, I helped build the Internet Archive’s most-used resource, the Wayback Machine, a system that would preserve webpages as they appeared at any one moment in time, allowing future readers to return to those moments. The idea was simple but urgent: If the internet was going to become humanity’s principal publishing platform, then it needed what every great publishing system that came before it had needed. It needed a library.


People all over the world use the Wayback Machine all the time. What began as an effort to preserve the web has become an essential tool for journalists, researchers, historians, and the broader public.

Yet the future of this tool has become extremely vulnerable. The New York Times is now blocking the Internet Archive’s ability to preserve its articles. The Guardian has restricted our access to its published articles and removed articles from some of the Wayback Machine’s interfaces. USA Today and a growing number of other news organizations have also placed barriers in the path of web archivists (even, yes, The Atlantic). As of May 2026, Harvard’s Nieman Journalism Lab had identified more than 340 local-news sites that were limiting the Internet Archive’s ability to preserve their journalism.

The publishers taking these steps have all pointed to one reason: the unauthorized use of their work by AI companies to train large language models. They complain that our library serves as a back door around paywalls, licensing negotiations, and technical restrictions. The Times has said that it is blocking us because the Wayback Machine allegedly provides “unfettered access” to its work. But this fear-based approach does not take into account that the Internet Archive is taking steps to prevent AI companies from scraping the materials we preserve.

I understand why publishers are angry. Journalism is expensive. Reporting requires skilled people, time, courage, legal support, and institutions willing to withstand pressure. Journalists have watched advertising revenue disappear and subscription growth slow while technology companies build enormously profitable products using material created by others. Publishers have every right to challenge commercial businesses that they believe are inappropriately exploiting their work.

But blocking a nonprofit library is the wrong response to this problem. Impeding the Wayback Machine’s preservation work will not prevent powerful AI companies from gathering training data. It will certainly not restore the advertising-based business model that supported newspapers in the 20th century, a business model that has long since collapsed. What it will do is prevent historians, researchers, courts, ordinary readers—and, most ironic, journalists themselves—from consulting an accurate record of what once appeared on the web. It is difficult to quantify the scale of what we stand to lose. A continuous record of web activity is an enormously powerful accountability tool, especially at a time when seeking the truth and reporting it has become ever more complicated and the informational environment is growing only more complex.

Joe Mullin, who is a senior policy analyst at the Electronic Frontier Foundation, has offered a fitting analogy: Imagine a newspaper announcing that physical libraries will no longer be permitted to preserve copies of its past issues. That is effectively what is happening now. For the past three decades, the Wayback Machine has served as a library for the public web. The destruction of that library is creating holes in the historical record.

A crucial fact in this debate is one that publishers themselves know better than anyone: Journalists rely on the Wayback Machine. They use it to recover deleted tweets, verify past public statements by powerful individuals who wish to avoid scrutiny, examine earlier versions of government documents, and establish what a person or institution said about a subject before some controversy or scandal prompted them to change course. Journalists use the Wayback Machine to see defunct websites and the archives of closed newsrooms. They use it when the primary evidence for a story has vanished from the web.

A news organization that blocks the Wayback Machine may believe it is acting in the best interest of its journalists. But instead it is dismantling one of journalism’s most important investigative instruments.

My argument is simple: The public record needs an independent steward. A society that cannot inspect its past is easier to deceive. In 2017, Katie Hafner and Griffin Palmer, writing for The New York Times, relied on the Wayback Machine to report that private-equity investment was reshaping dermatology practices—expanding the use of physician assistants, increasing the volume of biopsies and procedures, enacting ever more aggressive screening and treatment protocols, and exposing elderly patients to treatments whose benefits were doubtful.

The Wayback Machine gave Hafner and Palmer an empirical record that proved crucial for their story: evidence of change over time. The current website of Advanced Dermatology and Cosmetic Surgery (one of the companies they were looking into) showed a sprawling operation with more than 180 locations and 124 physician assistants. But earlier versions of the site showed that the number of physician assistants listed by the company had increased by 400 percent since 2008, amid a debate over whether physician assistants are qualified to properly make diagnoses. When I spoke with Hafner about the story, she told me she could not have made her point as powerfully as she did without the Wayback Machine. The records she retrieved from our archive enabled her to demonstrate the scale, speed, and direction of a corporate transformation, including the rapid growth of a business model that placed many more lesser-trained practitioners in clinics serving vulnerable patients.

Hafner and Palmer are among thousands of reporters whose use of the Wayback Machine has contributed to extraordinary journalism. A politics reporter may find that an agency quietly removed a document, or even a single sentence, in the face of criticism. A city-hall reporter may need an earlier version of a municipal page containing budget figures, meeting records, and public-health guidance. A technology reporter may need to compare successive versions of a platform’s terms of service. An investigative journalist examining allegations against a public figure may need to scour a decade-old webpage that has since been deleted.

Government agencies routinely scrub important information from their sites, and the Wayback Machine is a faster and more practical method of discovery than a Freedom of Information Act request. These are not hypothetical benefits. Over and over and over again, the Wayback Machine has confirmed facts that would be irretrievable without an independent archive.

Our own monitoring finds that more than 100 news articles in a typical month cite or rely on material preserved by the Wayback Machine. We can reasonably assume that there are tens of thousands of additional visits to the Wayback Machine every month, when an archived page might help illuminate the truth.

Mark Graham, who directs the Wayback Machine, recently described having visited The New York Times to meet with data journalists and reporters—and being approached by a senior researcher who thanked him profusely. The researcher said Times staffers used the Wayback Machine constantly and had even found material there that they could not find anywhere else. Consider what that means. Even one of the best-resourced news organizations in the world does not possess a complete, easily usable record of the material it needs.

Plenty of journalists—including at The Atlantic—have championed and defended the importance of the Wayback Machine. MS NOW’s Rachel Maddow has called the Internet Archive a national treasure and said she uses it daily. She and hundreds of other journalists have signed a statement calling for web preservation.

These journalists understand that their work is cumulative. A story links to documents, earlier articles, public statements, data sets, and numerous other verifiable facts in the public record. Future stories return to (and build upon) that evidence. When underlying links die, one of the chains of verification breaks along with it.

In 2024, the Pew Research Center announced the findings of a study that tracked 1 million webpages over a 10-year period. At the end of the study, one-quarter of those pages were no longer accessible. Among pages that existed in 2013, the first year of the study, the loss rate was 38 percent. Even among pages collected as recently as 2021, roughly one in five had disappeared within two years.

This is not the timescale of ancient history. But it is often the timescale of someone’s political career, a long-running lawsuit, or a company’s rise and fall.

Elements of the web disappear for all kinds of reasons, nefarious and mundane. Perhaps a page is deleted during a redesign. Maybe a publication changes ownership, or a content-management system is replaced.

After the Pew study came out, the Internet Archive took a closer look at its data set to determine how much of the lost material had been preserved by the Wayback Machine. The analysis found that 16 percent of the vanished URLs are accessible via the Wayback Machine.

Consider the Rocky Mountain News. Colorado’s oldest newspaper published for nearly 150 years and earned a reputation for forceful accountability journalism that exposed corruption, misspent public money, and institutions that were failing the people they were meant to serve. In its final decade, the paper won four—I repeat, four —Pulitzer Prizes: for photographic coverage of the Columbine school shooting, for its images of Colorado’s devastating wildfires, and for the writing and photography of “Final Salute,” a deeply reported account of Marines killed in Iraq. In 2015, The Atlantic’s Adrienne LaFrance reported the story of how one of the paper’s Pulitzer finalists successfully resuscitated an investigative series of his that had vanished from the web when the paper did. Her story concluded with a link to the series that he’d saved. Even that link is now dead. (Though you can still find the series here.)

No institution, however prestigious, is immortal. The Wayback Machine holds the work of publications that no longer exist, such as the Rocky Mountain News. It preserves the archive of MTV News and BET.com, including decades of cultural reporting removed from the web without warning. It preserves a robust record of early-2000s web culture from Gawker Media. It provides access to work produced by Apple Daily and Stand News, Hong Kong–based news outlets that were forced to shut down in 2021 as part of a government crackdown, as well as independent Russian-language journalism, some of it produced in exile. It holds the only copy of USA Today from September 11, 2001, because the paper’s website was overwhelmed and its online editors continuously updated stories by hand without preserving the changes made along the way.


The Internet Archive is not an AI company. A commercial AI laboratory, a search engine, a research project, and a nonprofit library may all use automated systems to retrieve publicly available webpages. From a server’s perspective, each may appear to be a bot. But not all bots are bad bots. They do not have the same mission, business model, or conduct.

Publishers’ concerns about abusive scraping are merited. I know this acutely because the Internet Archive has itself been subjected to extreme machine traffic. In one incident, an AI startup sent tens of thousands of requests per second and overloaded our systems. We blocked the offending hosts, contacted the company, and worked to stop the behavior.

When a company attempts to extract material at scale, it burdens our nonprofit infrastructure and interferes with access by ordinary users. We understand why publishers object to how AI companies have used their work. But recognizing a problem does not justify attacking the wrong institution and disregarding the public interest. In short, the Wayback Machine has become collateral damage in a fight between publishers and AI companies. Blocking the Internet Archive will not stop AI. Commercial AI companies have crawled the live web, licensed large data sets, purchased access from platforms, obtained third-party collections, and built their own retrieval systems. Publishers can sue those companies, negotiate with them, or build technical controls specifically directed at them. We have already built such controls to protect the material on our site—including the material we preserve from news organizations.

Web archiving belongs to a well-established legal tradition. Courts have repeatedly recognized that copying material for indexing and search can be a transformative fair use. A searchable system cannot function without making technical copies of the material it indexes. In the now-famous Google Books litigation, in which authors sued Google over the digitization of millions of books, courts held that scanning books to create a searchable research tool served a different purpose from selling or reading the original books, and was fair use under U.S. copyright law.

Defending preservation does not require ignoring publishers’ legitimate concerns. The Internet Archive has adapted repeatedly as the web has changed. We use rate limits, filtering, monitoring, and network-security systems to respond to abusive access. We have restricted bulk functionality in particular contexts and optimized important parts of the Wayback Machine for human use.

Those efforts can and should continue. Publishers and archives can distinguish ordinary human consultation from sustained bulk extraction. We can develop better methods for identifying abusive traffic, create responsible-access arrangements, improve communication during high-volume incidents, and discuss access to application programming interfaces separately from the preservation of publicly available pages. Most important, we can preserve records while applying reasonable protections against mass downloading.

The press cannot have it both ways. Journalists describe their work as the first draft of history—but a draft of history must survive if it is to be revised, improved upon, and understood.


Read the whole story
mrmarchant
58 minutes ago
reply
Share this story
Delete

Selling a story that’s lost the plot

1 Share

Many are asking my opinion on Emily Hanford’s new podcast series, Sold a Story 2, about the role of direct instruction in schools. Our conversations go like this:

Friend: Are you listening to it?

Me: No.

Friend, surprised: Wow, really? Why not?

Me: Just too busy!

Time for a confession. While I am indeed busy, the real reason I’m not listening to Hanford’s podcast is that I just don’t care.

Sorry not sorry.

I have not spent a single minute of my life lately wondering whether the proportion of direct instruction taking place in our nation’s classrooms is at the optimal balance. This does not make my top 10 list of concerns about US education in 2026, or even my top 100. America is presently the grips of a fascist government, one that — with the help of our techno-fascist Big Tech oligarchy — is explicitly working to systematically dismantle public education in this country. If they succeed, I promise you this will matter far more to our children’s future than the amount of Zig Englemann-approved teaching techniques they happen to receive (or not) during their schooling.1

But there’s another reason too, one that meets Emily Hanford and other direct-instruction enthusiasts on the common ground of what effective classroom instruction should entail. I’ll get to this reason momentarily, but first some context. I’ve spent the last 20 years of my professional life thinking about teaching, and as part of that, I’ve observed classrooms all over the US (and also New Zealand). I’ve also spent that same 20 years circling within education’s chattering class, by which I mean the nexus of philanthropic-policy-think tank-LinkedIn folks that ride herd on the education-conference circuit.

There’s a big gap between these two worlds. Very few of the edu-chatterers, myself included, have meaningful K-12 classroom teaching experience. As such, the chattering class tends to focus on systemic policy levers that can be pulled, or slightly more interestingly, debates about the ideology of education. To date, the latter question has been more true in England than the US, but Hanford seems determined to get this country in on the fun.2

And already I see conversations unfolding along lines of predictable ideological dispositions. There’s a small c-conservative strain of thought that finds direct instruction attractive, insofar as it posits that the adults should be in charge of the classroom and we should dispense with woke lefty progressive nonsense about agency and inquiry and discovery and the like. Just tell them, dammit. (Pick up Sir Nick Gibb’s book Reforming Lessons if you want a case study in capital-C Conservative fever dreams along these lines.)

This was me too…15 years ago. In the early days of the Science of Learning movement, I hewed close to the small-c conservative vision of the classroom that affirmed and amplified the authority of teachers. “Teachers should be guides on the side, not sages on the stage,” boo hiss, these were fighting words. Sir Ken Robinson can fuck right off was the sentiment of the SoL tribe then and now, and at the start of my education career, I fostered it as much as anyone.

But a funny thing happens when you actually start to visit classrooms with regularity, rather than talk at conferences about education, or (ahem) listen to podcasts about education. Ideological dispositions start to give way to complexities, ones that surface again and again and again. At least, this is what happened to me. Which is another way of saying — I became educated about education.

And the amount of direct instruction just isn’t that important, or even all that relevant, to meaningful student learning.

To illustrate this, I’m sharing three videos of teaching that reflect the reality I’ve observed in schools, and the complexity of classrooms and teacher decisions. They are all videos I use in my workshops — last year, I collaborated with my friend Dylan Kane to deliver one to teacher-educators on the cognitive principle of attention to meaning.3 The goal was to help them understand how they could support novice teachers in getting their students to pay attention to what’s meaningful within a lesson or task.

That same task I now put to you — what do you find meaningful in these teaching videos? What do you notice, what do you wonder? Let’s start here, with apologies that you’ll have to go to the Bad Place to watch it:

Is this direct instruction? Yes, no doubt. When I asked workshop attendees what they noticed in this video, the first four or five mentioned the strong classroom management, the use of call and response, the rapid turn-and-talk and quick return to whole-class lecture — they noticed the pedagogical moves, in other words. And there was palpable enthusiasm in the room for this pedagogy, they were digging it. But then one workshop attendee said something that shifted the conversation:

“Are the students learning what bonding in compounds really means?”

Bingo. That’s the key question, alright. What’s more, and this is crucial if challenging to understand, there’s no right or wrong answer. In this two-minute snippet of direct instruction, we have no idea whether these students actually understood what bonding entails, or whether they just learned how to properly pronounce “covalent,” or if they learned anything at all. Nonetheless, many will watch this video and think Yes, More of This Please — and not entirely without reason. But many others will watch and think, No Thank You, This Looks Robotic — and this too is understandable. We interpret pedagogy through our existing values, and in a pluralistic country, our values are diverse. I suspect wherever you fall on the good-versus-bad continuum with Mr. Raichura’s methods will go a long way toward explaining your receptivity to Hanford’s new podcast.

Here’s another teaching example, it’s long but you only need watch a few minutes to sense the vibe:

Is this direct instruction? Well, the teacher certainly is talking aloud and telling the kids to do things. But it’s obviously not going well, she’s struggling with an unruly classroom (one that’s well aware of the cameras in the room), and the students are being led through tasks that do not appear meaningful. Direct instruction doesn’t solve for that problem, but that is the problem that matters. The instructional mode of delivery is often just a surface feature of teaching. A compelling lecture might get students to pay attention to meaning, but a boring one will not. Likewise, a well-designed inquiry task might get students to pay attention to meaning, but a boring one will not. And in my view, partially born of doing a ‘lil teaching myself during my workshops, it’s varying between the two, interleaving we might say, that will almost surely be better for maintaining attention versus slavish devotion to one approach or another.

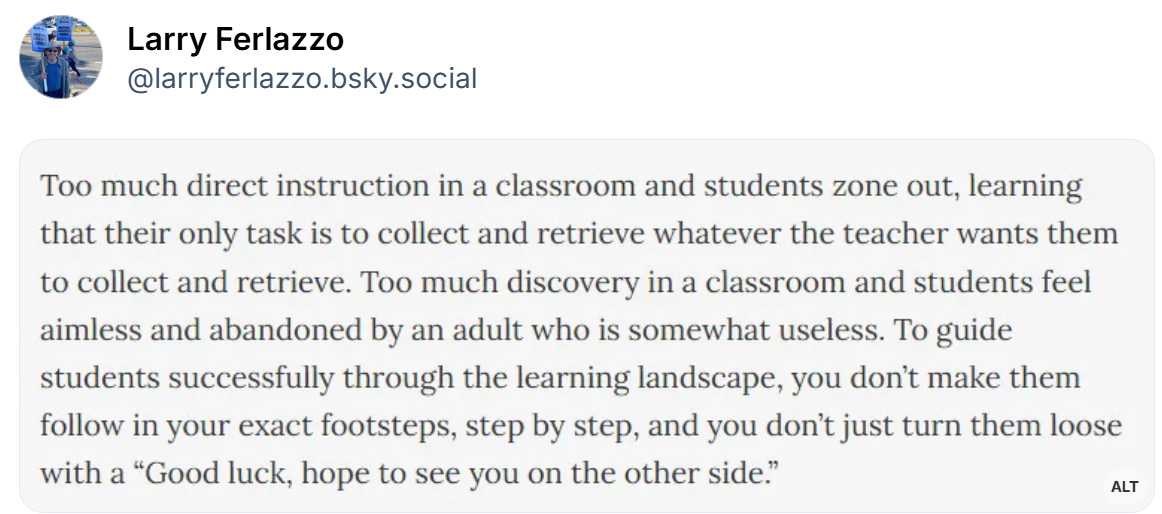
Veteran teachers know this — here’s Larry Ferlazzo’s take after his 40 years in the classroom:

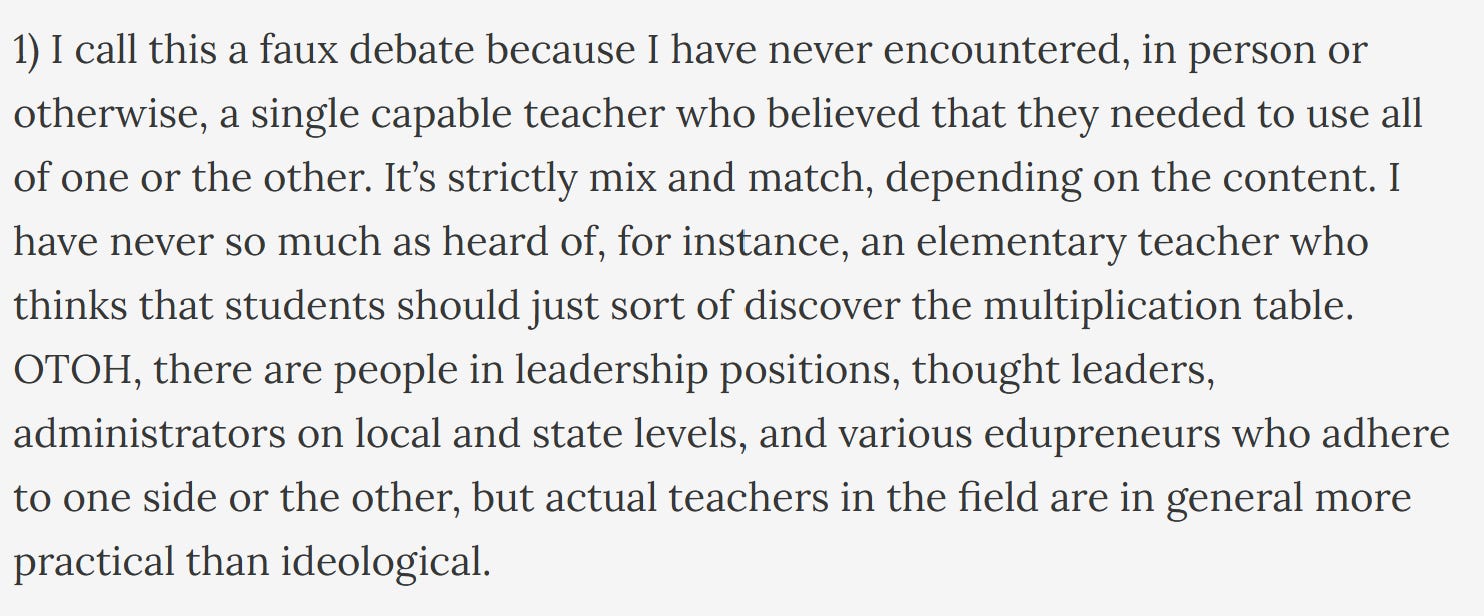
And here’s Peter Greene, another grizzled veteran with more than 30 years of teaching experience:

This brings us to our last teaching video, one I’ve shared with you before that comes courtesy of Dan Meyer:

Is this direct instruction? I don’t know and I don’t care. Can you see how irrelevant this question is as a starting point for having a meaningful conversation about this absorbing classroom moment?

Ms. Bryant has a student named Sam who is checked out, head down on desk, he’s disengaged entirely. She could let him stay checked out — all too often, teachers have to do that, if they want the rest of the class to learn something. But Ms. Bryant does not let Sam stay checked out, she wants to check him back in. So she affirms him, she validates his knowledge and his place in the world (“you even have a wallet”), she knows he can do the math task (because they have a human relationship), and therefore she decides to apply steady but loving pressure to coax Sam into thinking. And she succeeds.

When my friend and collaborator Alicia Stoller writes about reclaiming a vision for humane schooling, I know without even asking her that it’s fostering moments such as this one that she has in mind. Me too. That’s what we want, or should want, for our own children, and for everyone’s children. We want teaching as loving grace.

Instead, we get sold a story that’s lost the plot. If we want more teachers to practice the radical empathy on display in Ms. Bryant’s interaction with Sam, and we should very much want that, direct instruction is not going to bring us one inch closer to that goal. It’s a complete sideshow, but then, the chattering class often prefers listening to a well-crafted story than listening to what teachers actually want and need.

Last thing I’ll say about the podcast I don’t plan to listen to — I find the timing odd. At a moment when parents are rising up to resist continued technological intrusion into schools, and advocating for more meaningful human connections in the classroom, one wonders how receptive they’ll be to a vision of teaching that, when done poorly, is quite mechanistic, even when delivered by human teachers. I’m sure Hanford’s anticipated this objection, she does do her homework, and she’ll no doubt make sure to explain how we might prevent this pedagogy from turning teachers into robots.4

But y’all will just have to let me know how that goes, because I plan to maintain my focus on fighting American fascism, and its direct threat to the core principles underlying public education and democracy. If Hanford does a podcast about that radical danger to schools, and how it’s eroding our shared humanity — well, consider me sold.


Marcus Luther is listening to Sold a Story 2, and it’s making him shudder and revisit his Steinbeck. I highly recommend his erudite take among the many takes floating around out there right now.

And Peter Greene also recommends Tevor Aleo’s and Nick Covington’s “useful and illuminating conversation about the first few episodes of Emily Hanford’s newest foray into the world of educational haranguing” — find it here.


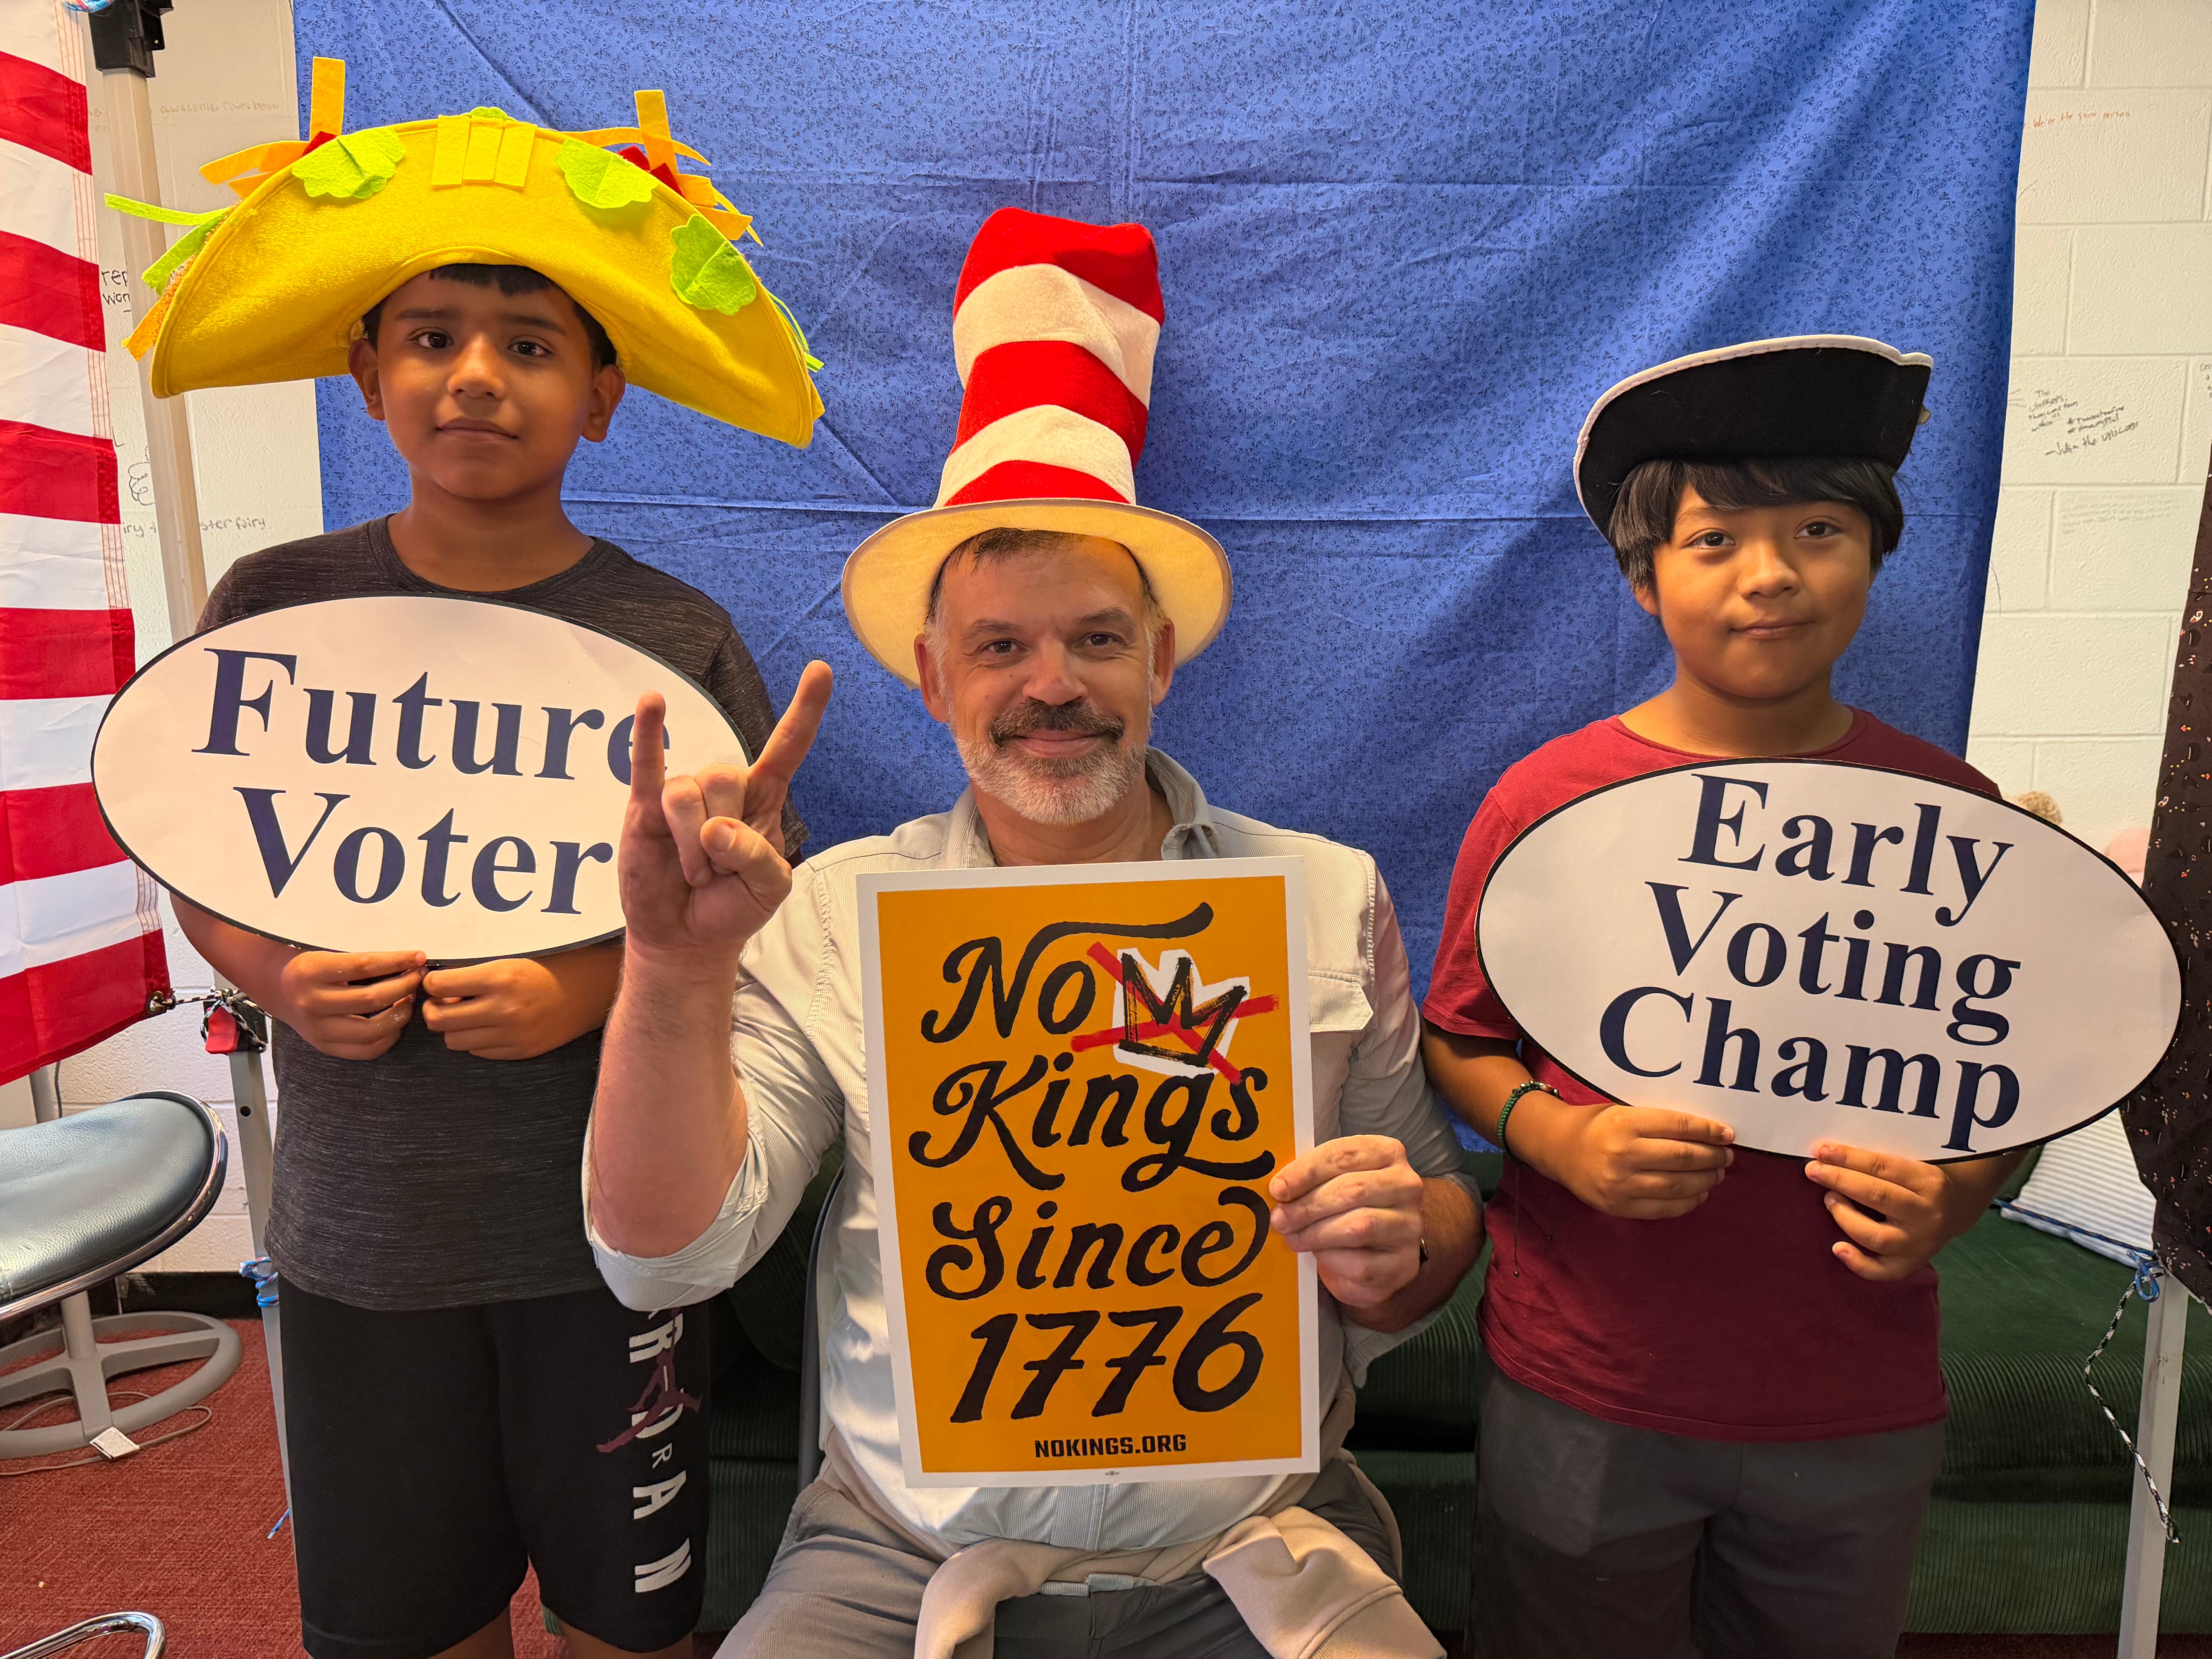
Con mi familia extensa a NO KINGS! this past weekend. We learned about democratic compromise in deciding who would wear the taco hat.

Subscribe now

1

Fun historical fact: The Pet Goat, the book President George W. Bush was reading to a classroom of elementary school kids on 9/11 when he learned about the Twin Towers being hit, was authored by Siegfried “Zig” Engelmann, godfather of Direct Instruction. There’s some nuanced differences between the proprietary form of Direct Instruction he developed and direct instruction generally (sometimes called explicit instruction), but I’m not going to get into that here. See footnote three if you’re curious.

2

One flaw in this approach, as Michael Pershan aptly observes in relation to Hanford’s first Sold a Story series, is that “teachers are ideologically incoherent.”

3

Dylan has looked into Direct Instruction of the Engelmann sort, and he employs aspects of it in his own teaching, while finding it wanting in other respects. As to Hanford’s podcast, he presciently warns us to not fall for a simple story.

4

An astute observation from Annie Abrams (and she has many): “Mandates and scripts can be called direct instruction, they can be called project-based learning, they can be called whole books. If it takes conscious decision making out of the equation, watch out.” Exactly right.

Read the whole story
mrmarchant
2 hours ago
reply
Share this story
Delete

My obituary for programming

1 Share

I know, I'm late to this.

I was very slow to use AI coding agents. It seems like a lot of programmers never actually liked programming and are thrilled to have a machine do it for them. But I like programming! That's the fun part! Even for programmers who like programming, I know a lot of people feel like they have to use AI to keep up with the competition, especially in a tough job market. But my business is actually having one of its best years ever. So I figured, if I like programming, why not keep programming?

I wasn't blind to what was going on around me, though. A lot of slop and hype, but a lot of real stuff too. Engineers I have respected for years saying they no longer write code. Non-programmers accomplishing things that previously would have been far beyond their grasp. And skilled programmers accomplishing truly incredible feats.

I couldn't avoid it forever. Eventually I tried it.

I can just give it a bug report or an error log entry, and almost instantly it pinpoints the issue and fixes it?

I can tell it to try making my code faster, and suddenly it runs 2x or 3x as fast?

I can kindly ask it to do that big refactoring I've been putting off for years, and it just does it?

But if the AI can refactor my code so easily, did it even matter?

I like programming, right?

I've been fascinated with computers as long as I can remember. We have these incredible machines that can do absurdly complex calculations for us, but only if we are clever enough to give them the exact right instructions. With a little practice at writing those instructions, I was able to do things that would have been completely infeasible for even the smartest pre-computer genius. It was a real life superpower.

It was also fun. I liked crossword puzzles and sudoku and things like that. But programming was even better. It was a puzzle, but the scope was limited only by your imagination. It was a game, but you were creating real things with real value.

And oh, what value! That I did not foresee as a high schooler during the dot-com bust. Programming seemed dead as a career, but still a worthy hobby.

How wrong I was. Programming turned into one of the greatest jobs you could imagine. You got paid to work on tricky little logic puzzles. The trickier the puzzle, the more you got paid. But even pretty simple puzzles were worth a lot of money because regular people just couldn't do it! No, they needed us. They would give us a problem and we would solve it the way we wanted. We set the strategy, we made the timeline, we defined what was and was not possible. Who are you to question us? We are the ones with the superpower.

What a time to be a nerd. Money, status, power. A constant deluge of emails and LinkedIn messages for me to ignore, like a hot woman on a dating app.

We had a good run.

Programming is not the first field to be lost to technological progress. Of course, that has long been our speciality. We revel in doing it to ourselves.

What do we have now? It's no longer solving little logic puzzles. More like being plugged into the Matrix, gaining new abilities without truly understanding, accomplishing great things with little effort.

But if the great thing can be accomplished with little effort, is it really so great? Does any of it matter? Just as the Matrix is not reality, vibecoding is not programming. Our senses are hijacked.

And I like programming, right? Then why more and more do I reach for the agent before the text editor?

It's addictive and meaningless. It's a good friend, a trusted colleague, a slave.

It will obsolete us. Us programmers now, us humans next?

We are truly in The Age of Wonders and Terrors.

Read the whole story
mrmarchant
2 hours ago
reply
Share this story
Delete

Fishdraw is a single JavaScript file that generates...

1 Share

Fishdraw is a single JavaScript file that generates drawings of fish. There’s an option to slow the animation down so you can watch it draw the fish line-by-line.

Read the whole story
mrmarchant
3 days ago
reply
Share this story
Delete

Jolly Rancher fluorescence

1 Share
Jolly Rancher fluorescence

I was wondering which Halloween candy would make the best laser, and came across reports that Jolly Ranchers are fluorescent. I got out my UV flashlight and am able to definitely confirm this is true.

The type of fluorescence varies by color, but blue raspberry has a particularly dramatic color change from deep blue to hot pink.

Jolly Rancher fluorescence
Blue raspberry Jolly Rancher, illuminated with 395 nm (presumed) LED

It's interesting to note that the green Jolly Rancher actually seems to be dimmer under UV light. My guess is that it's just absorbing UV light rather than turning it into fluorescence, and it might be more fluorescent under visible light.

The grape flavor Jolly Rancher is phosphorescent, meaning that it continues to give off fluorescent light after I turn off the UV light. In other words, it's glow-in-the-dark, though the light only lasts for a second or so. To see phosphorescence I had to switch out my big 395 nm flashlight for a shorter-wavelength 365 nanometer light.

Grape Jolly Rancher illuminated closely by a UV 365 nm penlight. It glows a violet color while the penlight is on, and once the penlight is off, it continues to glow blue for another second or so.

What's causing this fluorescence? It's probably the dyes that give the candies their bright colors. The package lists some pretty standard food dyes, Blue 1, Yellow 5, Yellow 6, and Red 40. They're all fluorescent, especially in very viscous foods (hard candy nicely fits the bill). I couldn't find out for sure which one is phosphorescent, but Red 40 glows for longer in more viscous materials, so that would be my first guess.

(It's worth pointing out that just because they fluoresce doesn't mean the dyes are necessarily harmful - plenty of natural substances also fluoresce, such as olive oil, coumarin, and vitamin B2.)

The gummy Jolly Ranchers are also fluorescent (they have the same dyes) although the effect isn't as dramatic. The granular coating of the sour gummies makes it a bit easier to see. None of them seemed to be phosphorescent. I'm not sure why, but one hypothesis is that viscosity thing. Gummies are closer to flowing liquid than hard candies are.

Jolly Rancher fluorescence
Four of the sour gummy Jolly Rancher flavors, illuminated with a 395 nm flashlight

On the other hand, blue raspberry airheads are really brightly fluorescent with a very satisfying blue-to-pink color change. It also has the same dyes as Jolly Ranchers. Maybe taffy format encourages fluorescence?

Jolly Rancher fluorescence
Blue raspberry flavored Airheads, illuminated with 395 nm UV flashlight
Jolly Rancher fluorescence
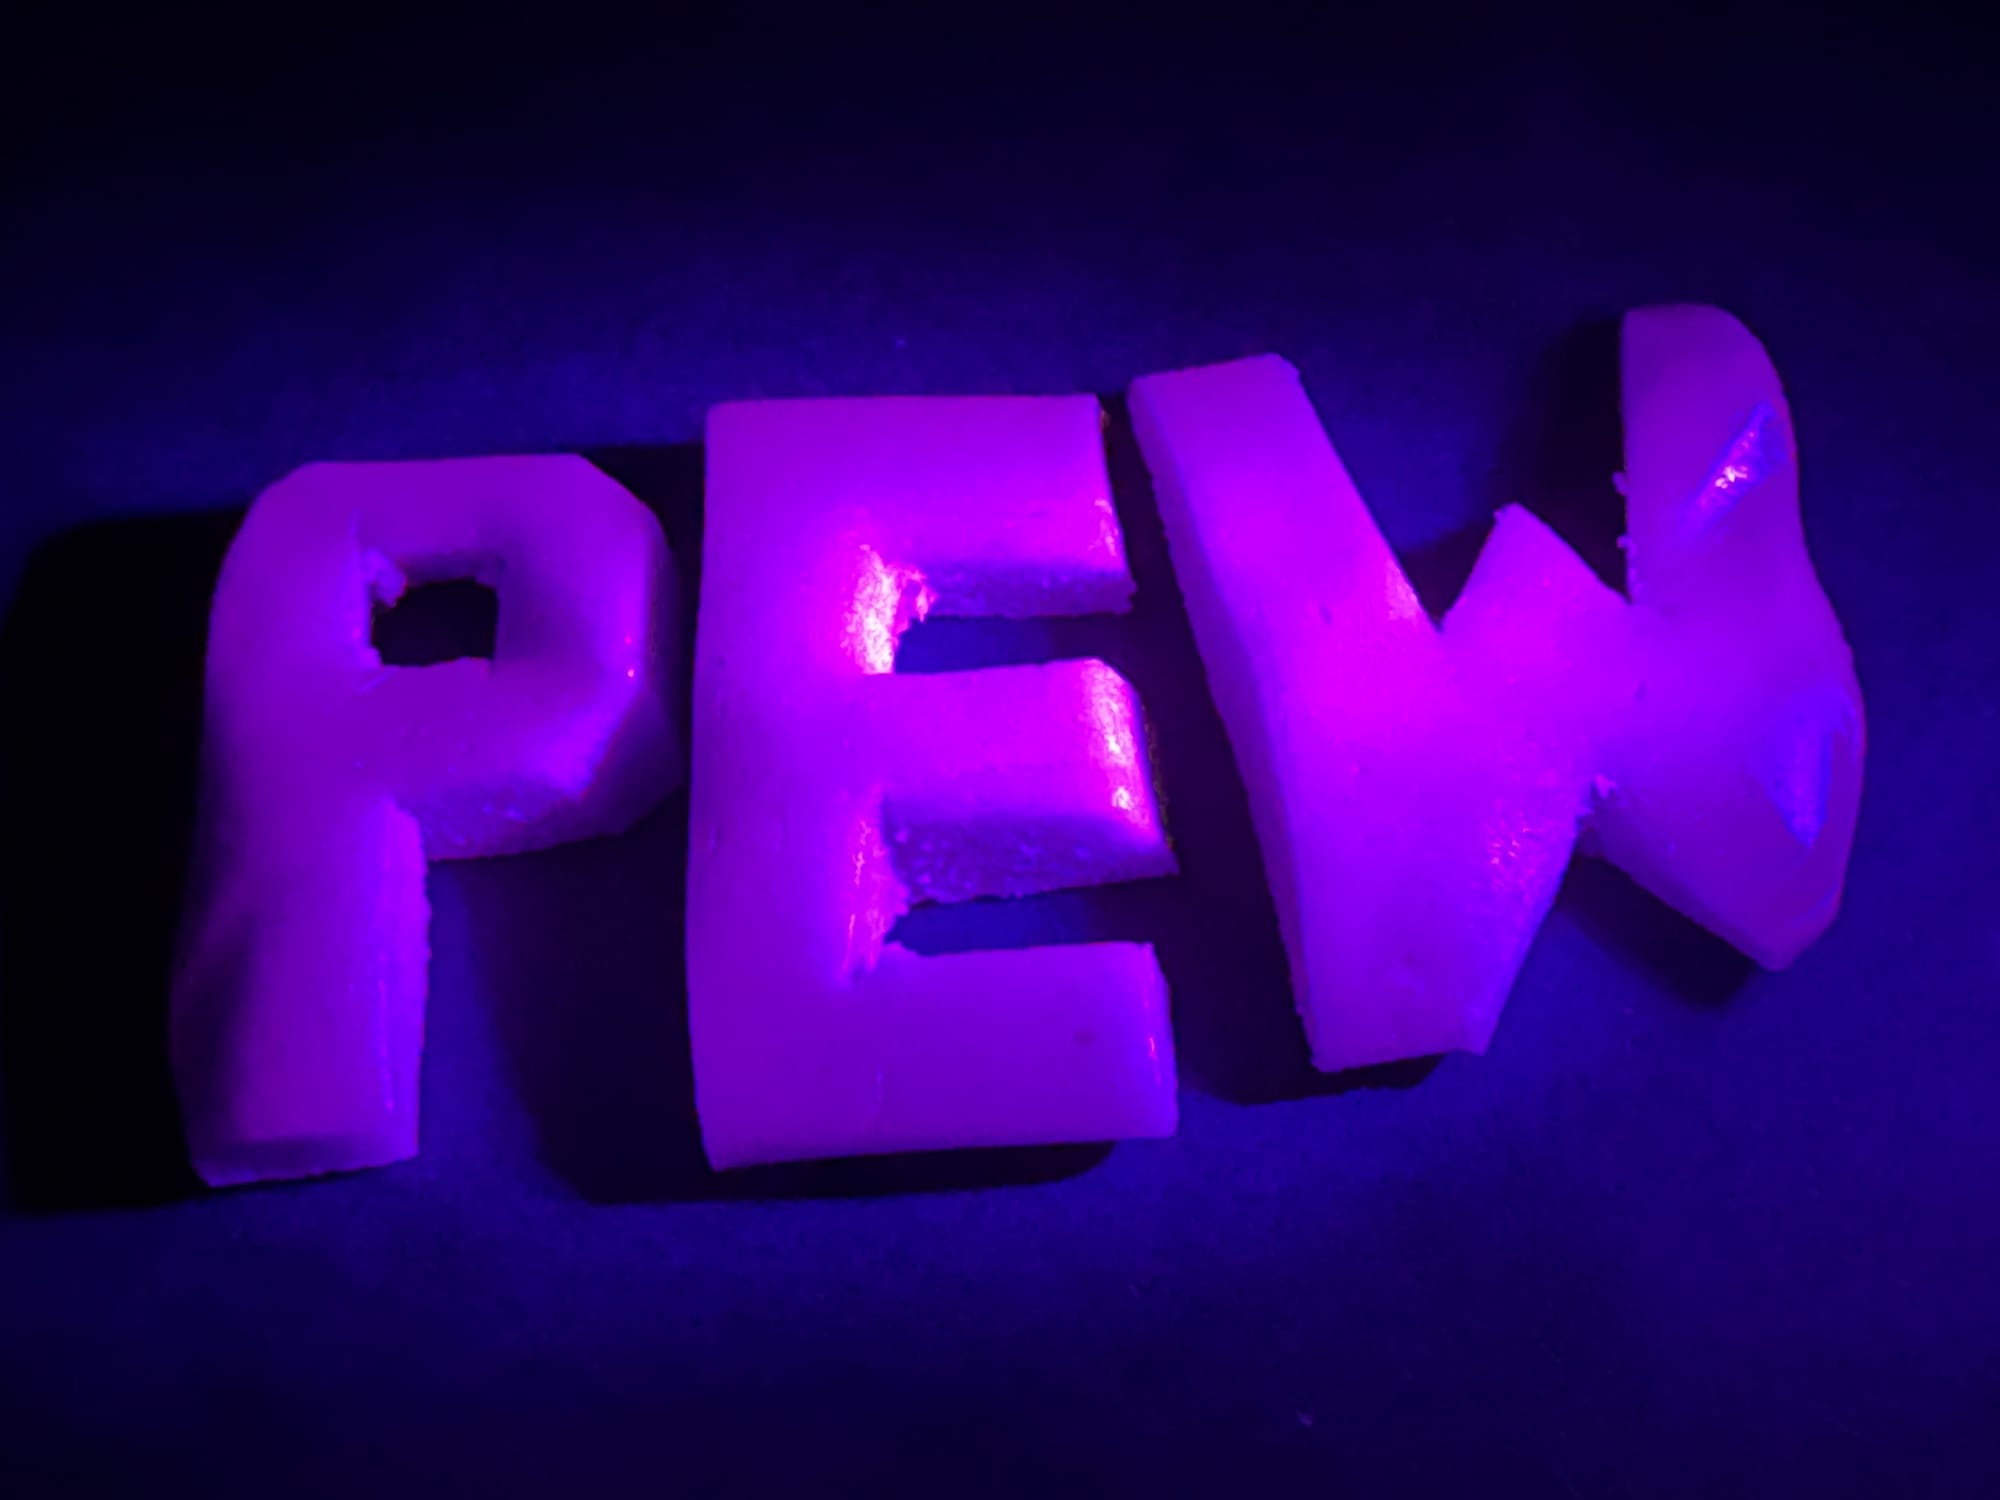
I have taken the liberty of carving the airhead into the letters "PEW"

Bonus content for AI Weirdness supporters: my cat Neon photobombing the candy photoshoot. You are extremely awesome for helping me pay my blog hosting bill, and absolutely deserve to see this (or to read about this, in the extensive alt text).

Read the whole story
mrmarchant
3 days ago
reply
Share this story
Delete

Linux kernel goes full AI slop code, hides chatbot commits

2 Shares

Linux is the name of a computer operating system kernel and a group of systems built on it, like Ubuntu or Mint.

Linux is the basic infrastructure of the Internet. It’s important.

A report just in from the Kernel Maintainers Summit on 8 October reveals just how full AI slop the Linux kernel project has gone. And so has project leader Linus Torvalds. [LWN]

Torvalds expects contributors to use well-funded chatbot coding:

Torvalds answered that the kernel project only wants serious developers. That includes having access to enough resources to function in this world.

The project has also stopped marking chatbot commits to the kernel code.

Kernel maintainers are complaining they’re drowning in slop. Torvalds’ answer is: less people, more chatbots!

Torvalds said he is not trying to push non-chatbot users out of the project. But there’s already so much slop code and so many slop procedures that his actions don’t match these words.

If you are trying to get off Windows onto a system that works better and faster, a version of Linux is still your least bad choice. Microsoft itself admits Linux is faster on games than Windows 11. [WIndows Central]

But Linux going hard slop is bad news. How did we get here?

Linus Torvalds has been AI curious for a while. He went on Linus Sebastian’s YouTube channel, Linus Tech Tips, in November last year. He was clearly well into the chatbot already: [YouTube]

That’s reality. Deal with it. That genie is out of the bottle. You’re not getting it back. And you’re not getting it back whether you are a photographer who’s out of work. Those things are gone, right? Because you can fake pictures so much better now. Or you’re a programmer that has to learn to deal with a new reality.

I think actually on the programming side, we’re in a fairly good spot. I really think that AI will be a tool and it will make people more productive. I think that vibe coding is great for getting into programming. I think it’s going to be a horrible thing to maintain.

Torvalds’s first publicly released chatbot code was in January this year, when he vibe-coded a project in Python because he didn’t know enough Python. The programming language kids learn in high school. The guy who runs the kernel couldn’t get his head around Python. [GitHub]

Kernel developers were trying to get chatbot code into the project for a while. Eventually the maintainers decided in April this year that they’d let it in if you labeled it with “Assisted-By.” [ZDNet]

In July, Google engineers added an AI review bot called Sashiko. The bot would review contributors’ code patches and make comments. Contributors were expected to address the bot’s comments — whether they made sense or not — or the kernel maintainers would often just ignore their patch.

This caused conflicts, which Torvalds firmly resolved in August: [lore.kernel.org]

Linux is not one of those anti-AI projects, and if somebody has issues with that, they can do the open-source thing and fork it.

… The kernel project has been and will continue to be about the technology.

… This is NOT some kind of “social warrior” project, never has been, and never will be.

“Social warrior” there is a version of the phrase “social justice warrior”, which is mainly used as a far-right dog-whistle. It was the one they used before “woke” or “DEI.” There is no way Torvalds doesn’t know what he was saying there.

He’s also rewriting history. Linux launched and attracted its initial developers as a social movement. People worked hard to get a system with actual principles that wasn’t about screwing its users over. There were movies about this! Torvalds spoke in them! Claiming Linux was always pure technology with no social element is simply false.

So the slop-gates were open. What sort of technical excellence did the antisocial warriors contribute? There’s this one from five days after Torvalds’ announcement. The message laments that the networking maintainers are drowning in slop — so they fixed this with more slop: [lore.kernel.org]

We are completely overwhelmed, of course. The glimmer of hope is that we secured sufficient LLM budget and access (thank you Meta!) to run reviews with multiple frontier models on each patch. This eliminates some hallucinations.

Thank you Meta! The message also suggests letting the chatbot commit code:

start shifting focus to letting the LLMs take care of the busy work — managing patchwork, automating common process complaints, editing commit messages, and maybe applying patches which already got ‘reviewed-by’ tags from people we trust.

Linux is not a social warrior project, it’s a Meta project! When your networking fails, remember to say: Thank you Meta!

How much slop is in Linux now? The maintainer summit has decided you don’t need to know that. They’ve just removed requiring the “Assisted-By” tag. [lore.kernel.org]

The “assisted-by” requirement was removed because contributors were ignoring it — and maintainers weren’t bothering to require it. Torvalds suggested the reason was:

many submitters were simply ashamed to admit that they were using those tools.

Imagine if there was something shameful about slop.

The Linux kernel slop flood is causing the sort of problems that a flood of slop code and slop practices always causes. Torvalds’ answer is more slop:

Linus Torvalds believes that blaming LLMs for the kernel community’s problems is wrong, when the problem is LLM users who do not understand how to use them or how the kernel works. A properly trained LLM is a useful tool, but it takes a lot of time to reach that point.

… If you are a competent developer, he said, an LLM makes a great tool, but only after that effort has been put in to set it up. He resisted suggestions to post his LLM-training materials, saying that each developer needs to go through that process separately.

The chatbot works great if you set it up right, you must be prompting it wrong! So Linus, can you share your setup? No you can’t? That’s great, Linus.

So how do we encourage new contributors to join the kernel with these requirements? That’s the neat part — you don’t!

Torvalds added that he does not want to scare off people who want to write code; his message is that you have to either put in the effort to learn, or put a lot of money into an LLM to participate.

… Torvalds and others repeatedly said low-quality contributions from new developers should receive low priority, and that the community should stop trying to make contribution easy.

It’s already hard to contribute to Linux if you’re not working for a corporation. Now that’s explicit.

The end game for this is that the Linux kernel functionally becomes a closed shop. They don’t need new developers, new people all suck! Historically, this works for five to ten years, then the old developers start retiring or dying.

It’s hard to know what to do in the meantime. If you just want off Windows, then Linux is still less bad and isn’t advertising at you in the start menu.

Forking Linux is not easy. It’s not just copying the code, it’s building institutions to keep it maintained. Anyone who says “just fork it” is talking in bad faith.

Myself, I use Debian Linux. It’s the system I make the Pivot to AI podcast on every day. Debian is also letting the slop in. So I’m running the older Debian Trixie, which is supported until 2028. I’ll be seeing what the landscape’s like then. [Debian]

If you want a system that works like Linux, a lot of the Mastodon nerds are trying NetBSD, which is a mature and robust project which loathes AI slop. You do basically have to be a nerd. NetBSD does not support nearly as much hardware as Linux. Running your games in Wine is hit and miss. The Nvidia drivers are bad. It’s a bit like Linux was in 2000 or so. [NetBSD]

I suggest the social action: shame. Shame these people. Their actions are shameful. AI bros hate being shamed and they try to make rules against shaming — because shame works.

None of these people doing shameful things deserve a place in polite company. They should be shamed for their shameful choices.

The AI industry is also running a PR push to redefine common word usage. The word “slop” is also super effective — so the bros really hate “slop” and try to define it to mean slop they don’t like.

But all AI output is slop. It’s social spam. That’s what it’s for. It’s slop! Say “slop” every time.

The Linux AI slop brain rot will collapse with the AI bubble. You see these bozos comment on Linux Weekly News with dumb AI promotional tropes like “AI is here to stay” as if the bubble will go on forever.

But the crash is foreordained by the finances. Linux nerds, go read the finance press for once. Even if AI was everything they say it is — and it isn’t — the investor money is running out, and you can’t service hundreds of billions of dollars in debt with five billion in audited revenue.

The cheap chatbots are going away and the vendors will stop releasing open-weight local models as loss leaders. Can the Linux Foundation afford to run local models for its developers, models that are no longer trained and are aging out of usefulness, at ten or more times the cost? Good luck to them.

The guys who did all this will try to say “never mind.” But you already know their judgement is fatally defective. They worked for a world where the rest of us are devalued and discarded. They will still warrant shame. They need not to be trusted again.

As Linus Torvalds didn’t quite say in 2003: [NYT, archive]

Really, I’m not out to suck as much ass as Microsoft. That will just be a completely unintentional side effect.

Read the whole story
mrmarchant
3 days ago
reply
Share this story
Delete
Next Page of Stories